What Is DNS and How It Works (Domain Name System Explained From Root to Resolution)

Understanding what is DNS and how it works is essential to understanding how the internet functions at all.

Every time you type a website name into your browser, send an email, or open an app, DNS is the first system that must respond before anything else can happen.

This guide explains what DNS is and how it works from the ground up — covering domain names, root servers, resolvers, caching, performance, security, and why DNS is one of the most critical pieces of global internet infrastructure.

DNS Is the Internet’s Phone Book — But Smarter

Every time you visit a website, send an email, or open an app, one system quietly runs first.

Before data can move, before servers can respond, before anything loads, DNS must work.

DNS — the Domain Name System — is what allows humans to use names like:

  • google.com
  • netflix.com
  • example.org

Instead of raw numerical IP addresses.

Without DNS:

  • The internet would still function
  • But only for machines
  • And only for people willing to memorize numbers

DNS is not just a convenience layer.
It is core internet infrastructure.

This article explains DNS from first principles:

  • What DNS actually is
  • Why it exists
  • How resolution works step by step
  • Where performance and failures come from
  • How modern DNS scales globally
  • Why DNS is also a security boundary


What DNS Actually Is

At its core, DNS is a distributed, hierarchical naming system.

It answers one fundamental question:

“Given a human-readable name, what network address does it map to right now?”

DNS maps:

  • Domain names → IP addresses
  • Services → locations
  • Human intent → machine routing

It does this without central control, at global scale.


DNS Is Not a Database

A common misconception is that DNS is a single global database.

It is not.

Instead, DNS is:

  • Distributed across many servers
  • Delegated by hierarchy
  • Cached aggressively
  • Updated continuously

No single system “knows” all DNS answers.


DNS Is a Translation System

DNS does not deliver content.
It does not route packets.
It does not host websites.

DNS only tells you where to go next.

Everything else depends on that answer.

Why DNS Exists

To understand DNS, you need to understand the problem it solves.


Machines Prefer Numbers

Networks route data using IP addresses.

An IP address:

  • Identifies a device or service
  • Is efficient for machines
  • Is terrible for humans

Example:

  • 142.250.190.14 means nothing to most people

Humans Prefer Names

Humans think in:

  • Brands
  • Words
  • Meaningful labels

DNS bridges this gap by allowing:

  • Stable names
  • Changing addresses
  • Decoupling identity from location

This decoupling is critical.


Why Hardcoding Addresses Doesn’t Work

Without DNS:

  • Changing servers would break links
  • Load balancing would be impossible
  • Failover would be manual
  • Global scale would collapse

DNS enables flexibility at internet scale.


Domain Names Explained

A domain name is a structured identifier.

Example:

www.example.com

Each part has meaning.

Reading a Domain Name Right to Left

Domains are read from right to left, not left to right.

www → subdomain example → domain .com → top-level domain (TLD)

The rightmost part is the highest level.

This hierarchy is the backbone of DNS.

Why This Hierarchy Matters

Hierarchy allows:

  • Delegation of control
  • Distributed responsibility
  • Independent administration

No single entity owns all domains.


The DNS Hierarchy: Who Answers What

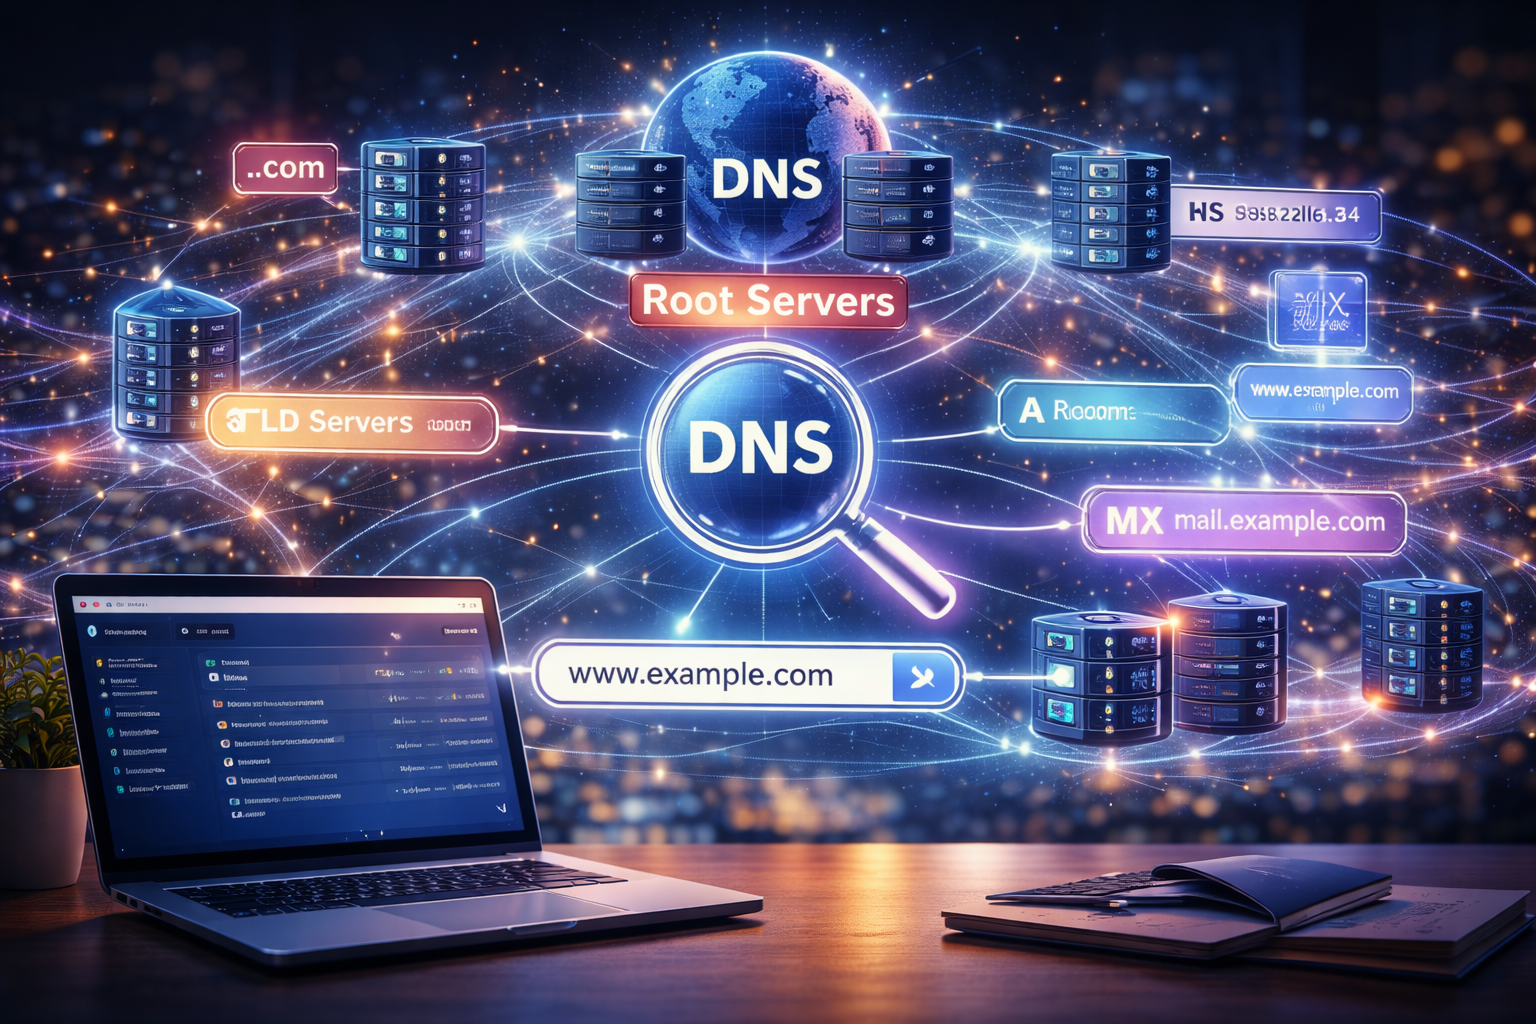
DNS resolution works by walking down the hierarchy, not up.

There are four major levels.


1. Root Level

At the top is the DNS root.

The root:

  • Knows where TLDs are
  • Does not know individual domains
  • Is extremely stable

There are only 13 logical root server identities, distributed globally.


2. Top-Level Domains (TLDs)

TLDs include:

  • .com
  • .org
  • .net
  • .io
  • Country codes like .uk, .de

TLD servers:

  • Know where domains are registered
  • Do not know subdomains

3. Authoritative Name Servers

These servers:

  • Are responsible for a specific domain
  • Contain the actual DNS records
  • Provide definitive answers

This is where truth lives.


4. Recursive Resolvers

Resolvers:

  • Perform lookups on behalf of users
  • Cache results
  • Speed up future queries

Your ISP or device typically uses a resolver.

What Is DNS and How It Works DNS Resolution: Step-by-Step

Let’s walk through what happens when you type:

example.com

Step 1: Local Cache Check

Before asking the internet, your device checks:

  • Browser cache
  • OS cache
  • Local DNS cache

If found, resolution stops here.


Step 2: Recursive Resolver Query

If not cached, your device asks a recursive resolver:

“Do you know the IP for example.com?”

If the resolver knows, it answers immediately.


Step 3: Root Server Query

If not, the resolver asks a root server:

“Who handles .com?”

The root replies with:

“Ask these .com servers.”


Step 4: TLD Server Query

The resolver asks a .com server:

“Who handles example.com?”

The TLD replies with:

“Ask these authoritative servers.”


Step 5: Authoritative Server Query

The resolver asks:

“What is the IP for example.com?”

The authoritative server replies with the answer.


Step 6: Caching and Return

The resolver:

  • Caches the answer
  • Returns it to your device

Only then does your browser connect to the server.

What Is DNS and How It Works DNS Records: What DNS Actually Stores

DNS doesn’t store “websites.”
It stores records.

Each record answers a specific question.


A Records and AAAA Records

  • A → IPv4 address
  • AAAA → IPv6 address

These map names to IPs.


CNAME Records

CNAME means:

“This name is an alias for another name.”

Used for:

  • Load balancing
  • Service abstraction
  • Infrastructure flexibility

MX Records

MX records specify:

  • Mail servers
  • Email routing priority

Without MX records, email doesn’t work.


TXT Records

TXT records store:

  • Verification data
  • Security policies
  • Metadata

They are heavily used in modern security systems.

What Is DNS and How It Works Caching: Why DNS Is Fast

DNS would be unusably slow without caching.

Caching happens at:

  • Browser level
  • OS level
  • Resolver level
  • ISP level

TTL (Time To Live)

Every DNS record includes a TTL.

TTL controls:

  • How long a result is cached
  • How quickly changes propagate
  • The trade-off between freshness and performance

Low TTL:

  • Faster updates
  • More queries

High TTL:

  • Better performance
  • Slower changes

Why DNS Failures Are So Disruptive

When DNS fails:

  • Websites appear offline
  • Apps stop working
  • Services seem “down”

Even when servers are fine.

DNS is a single dependency with global impact.

What Is DNS and How It Works DNS Performance: Why Resolution Is Usually Fast

At first glance, DNS resolution looks slow.

One lookup appears to involve:

  • Multiple servers
  • Multiple round trips
  • Global communication

Yet in practice, DNS lookups usually take milliseconds.

That speed comes from aggressive caching and smart distribution.


Where DNS Caching Happens

DNS answers are cached at many layers:

  1. Browser cache
  2. Operating system cache
  3. Local network cache (router)
  4. Recursive resolver cache
  5. ISP cache

Most DNS queries never leave your local network.

DNS requests are also important in secure networking systems such as VPN connections, where DNS traffic may be routed through encrypted tunnels.


Why Most DNS Queries Never Reach Root Servers

Root servers only see a tiny fraction of total DNS traffic.

This is because:

  • TLD answers are cached
  • Authoritative answers are cached
  • Resolvers reuse answers across many users

The hierarchy is designed to push load downward, not upward.


Cold vs Warm DNS Lookups

  • Cold lookup: Nothing cached → full resolution path
  • Warm lookup: Cached answer → instant response

Most user experiences rely on warm lookups.

What Is DNS and How It Works Latency in DNS: What Actually Slows It Down

When DNS feels slow, it’s rarely because of DNS itself.

Common causes include:

  • Poorly located resolvers
  • Network congestion
  • High-latency last-mile connections
  • Misconfigured TTL values

DNS adds overhead — but it’s usually not the bottleneck.


Why Distance Still Matters

DNS resolution involves round trips.

Physical distance affects:

  • Time to root servers
  • Time to authoritative servers
  • Time to resolvers

This is why global DNS infrastructure focuses heavily on geographic distribution.


What Is DNS and How It Works Anycast: How DNS Scales Globally

One of the most important — and least understood — DNS technologies is anycast.


What Anycast Is

Anycast allows:

  • Many servers
  • In many locations
  • To share the same IP address

When you query that IP:

  • The network routes you to the nearest available server
  • Based on routing topology, not geography

Why Anycast Is Perfect for DNS

DNS traffic:

  • Is read-heavy
  • Is stateless
  • Can tolerate some inconsistency

Anycast enables:

  • Low latency
  • High redundancy
  • Massive scalability

This is how a small number of logical servers handle billions of queries per day.

What Is DNS and How It Works Authoritative DNS vs Recursive DNS

It’s important to distinguish between two very different DNS roles.


Authoritative DNS Servers

These servers:

  • Hold the official records
  • Answer definitively
  • Are controlled by the domain owner

They do not cache answers from others.


Recursive DNS Resolvers

These servers:

  • Act on behalf of users
  • Perform full resolution
  • Cache results aggressively

They trade freshness for speed.


Why This Separation Matters

Separating roles:

  • Improves scalability
  • Limits blast radius
  • Enables independent optimization

DNS is resilient because no single server type does everything.


DNS and Load Balancing

DNS is often used as a traffic steering mechanism.


Simple Load Balancing

DNS can return:

  • Different IPs
  • In different orders
  • Based on location or policy

This spreads load across servers.


Geographic Routing

DNS can direct users to:

  • The nearest data center
  • The lowest-latency region
  • A region with spare capacity

This improves performance and reliability.


Limitations of DNS Load Balancing

DNS decisions are:

  • Cached
  • Slow to change
  • Blind to real-time server health

This is why DNS is often combined with:

  • CDNs
  • Load balancers
  • Health checks

What Is DNS and How It Works DNS and Content Delivery Networks (CDNs)

DNS plays a critical role in how CDNs work.


How DNS Enables CDNs

When you request content:

  1. DNS directs you to a CDN domain
  2. The CDN’s DNS system evaluates your location
  3. You receive an IP for a nearby edge node

This all happens before any content is requested.


Why DNS Is the First Decision Point

DNS decides:

  • Which network you hit
  • Which region serves you
  • Which cache layer responds

By the time HTTP begins, the path is already chosen.


DNS as an Optimization Layer

Modern DNS systems:

  • Integrate performance data
  • Adapt to network conditions
  • Shift traffic dynamically

DNS is no longer just naming — it’s traffic intelligence.

DNS Security: Why Naming Is a Target

Because DNS sits at the front of every connection, it is a high-value attack surface.


DNS Spoofing and Cache Poisoning

Attackers may try to:

  • Inject fake DNS answers
  • Redirect users to malicious servers
  • Intercept traffic

This is called DNS poisoning.

It works by exploiting trust in cached answers.


Man-in-the-Middle Attacks

If DNS is compromised:

  • Users can be redirected
  • Even if websites themselves are secure

This makes DNS a critical link in the security chain.


Why DNS Was Vulnerable Historically

DNS was designed:

  • Before widespread security threats
  • Without built-in authentication
  • With implicit trust between servers

Security had to be added later.


What Is DNS and How It Works DNSSEC: Securing DNS Answers

DNSSEC (DNS Security Extensions) addresses DNS authenticity.


What DNSSEC Does

DNSSEC allows resolvers to:

  • Verify that DNS answers are genuine
  • Detect tampering
  • Reject forged responses

It uses:

  • Cryptographic signatures
  • Chains of trust
  • Public key verification

What DNSSEC Does NOT Do

DNSSEC does not:

  • Encrypt DNS queries
  • Hide which domains you visit
  • Prevent all attacks

It ensures integrity, not privacy.

What Is DNS and How It Works DNS Privacy: Who Sees Your Queries

Traditional DNS is sent:

  • In plaintext
  • To your resolver
  • Over the network

This means DNS queries can be observed by:

  • ISPs
  • Network operators
  • Intermediaries

DNS reveals intent, even when content is encrypted.


Encrypted DNS (DoH and DoT)

Modern approaches include:

  • DNS over HTTPS (DoH)
  • DNS over TLS (DoT)

These encrypt DNS queries in transit.


Privacy Trade-Offs

Encrypted DNS:

  • Improves privacy
  • Centralizes trust
  • Shifts power to resolver providers

Privacy gains come with new dependencies.

What Is DNS and How It Works DNS and Tracking

DNS can be used for tracking and attribution.

Examples include:

  • Unique subdomains per user
  • Short-lived DNS records
  • Correlating query timing

DNS-based tracking is:

  • Indirect
  • Hard to block
  • Often invisible to users

This makes DNS both powerful and sensitive.

Operational DNS Failures

DNS failures tend to be systemic, not isolated.

Common causes:

  • Configuration errors
  • Expired domains
  • Registrar mistakes
  • Mis-set TTLs
  • DDoS attacks on DNS infrastructure

Because DNS is upstream of everything, failures propagate widely.


Why DNS Changes Feel Slow

When you change DNS:

  • Old records persist due to caching
  • Different resolvers update at different times
  • Global consistency takes time

This is not a flaw — it’s a consequence of scale.


Modern DNS Trends

DNS continues to evolve.

Key trends include:

  • More encryption by default
  • Smarter traffic steering
  • Integration with security systems
  • Edge-aware resolution
  • Greater regulatory scrutiny

Despite changes, the core model remains intact.


Mental Models for Understanding DNS

To reason clearly about DNS, keep these in mind:

  1. DNS is distributed, not centralized
  2. Caching is the reason DNS scales
  3. DNS answers “where,” not “what”
  4. Security and privacy are separate concerns
  5. DNS failures are disproportionately visible

What Is DNS and How It Works Frequently Asked Questions

Is DNS required for the internet to work?
Yes — for humans. Machines can use IPs directly, but almost no systems do.

Can DNS be bypassed?
Technically yes, practically no at scale.

Why does DNS take time to update?
Because caching is necessary for performance and resilience.

Is changing DNS servers safe?
Usually, but it changes who you trust with your queries.


What Is DNS and How It Works Conclusion: What DNS Really Does

DNS is often described as the internet’s phone book.

That analogy understates its importance.

DNS is:

  • A global coordination system
  • A performance optimization layer
  • A security boundary
  • A privacy consideration
  • A critical dependency for almost everything online

Every click begins with DNS.

When DNS works, no one notices.
When DNS fails, everything breaks.

Understanding what DNS is and how it works reveals just how much of the internet depends on one quiet, distributed system doing its job perfectly, billions of times per day.

What Is DNS and How It Works Deep Dive: DNS Failure Modes and Recovery Patterns

DNS failures are uniquely disruptive because everything depends on them. When DNS breaks, the internet appears broken—even if servers and networks are healthy.

Understanding failure patterns is the key to designing resilient DNS.


Failure Mode 1: Configuration Errors

The most common DNS outages are self-inflicted.

Examples:

  • Typo in a record
  • Incorrect IP address
  • Missing record
  • Wrong TTL value
  • Broken delegation to name servers

Why this is dangerous:

  • DNS changes propagate globally
  • Caching amplifies mistakes
  • Rollbacks are slow

Recovery strategies

  • Staged rollouts with low TTLs
  • Change validation and linting
  • Dual-provider DNS (where feasible)
  • Explicit delegation checks

Failure Mode 2: Expired Domains

When a domain expires:

  • DNS stops resolving
  • Email fails
  • Services disappear instantly

This failure is:

  • Sudden
  • Public
  • Preventable

Recovery strategies

  • Auto-renewal at registrars
  • Multiple administrative contacts
  • Domain expiration monitoring

Failure Mode 3: DNS Provider Outages

Even highly reliable DNS providers can fail.

Causes include:

  • Software bugs
  • Control plane failures
  • DDoS attacks
  • Misrouted traffic

Because DNS is centralized per domain, provider outages can be catastrophic.

Recovery strategies

  • Secondary DNS providers
  • Anycast diversification
  • Split-horizon DNS (advanced)
  • Regular failover testing

Failure Mode 4: DDoS Attacks on DNS

DNS is a common DDoS target because:

  • It’s publicly reachable
  • It’s essential
  • Small queries can amplify traffic

Recovery strategies

  • Anycast distribution
  • Rate limiting
  • Response caching
  • DDoS mitigation services

DNS in Enterprise Environments

Enterprise DNS is more complex than public DNS.

It must handle:

  • Internal services
  • Private networks
  • Split-horizon resolution
  • Security policies
  • Compliance requirements

Internal vs External DNS

Enterprises often maintain:

  • Internal DNS for private resources
  • External DNS for public-facing services

The same domain name can resolve differently depending on:

  • Network location
  • User identity
  • Security context

This is called split-horizon DNS.


Why Enterprises Rely Heavily on DNS

DNS is used for:

  • Service discovery
  • Failover
  • Microservice routing
  • Policy enforcement

In many organizations, DNS becomes a control plane, not just a naming system.


Operational Risks in Enterprise DNS

Risks include:

  • Shadow DNS changes
  • Manual configuration drift
  • Poor documentation
  • Overlapping namespaces

Enterprises mitigate this with:

  • Infrastructure-as-code
  • Change management
  • Observability and logging

DNS in Cloud Environments

Cloud computing has reshaped DNS usage.


Dynamic Infrastructure Changes

In the cloud:

  • Servers are ephemeral
  • IPs change frequently
  • Scaling happens automatically

DNS enables:

  • Stable naming
  • Service abstraction
  • Dynamic routing

Without DNS, elastic infrastructure would be unmanageable.


Service Discovery via DNS

Cloud systems often use DNS to:

  • Locate services
  • Balance load
  • Enable zero-config communication

Examples include:

  • Database endpoints
  • Internal APIs
  • Regional services

DNS becomes the glue that holds microservices together.


Private DNS Zones

Cloud providers support:

  • Private DNS zones
  • Isolated name resolution
  • Network-scoped visibility

This allows:

  • Security isolation
  • Clean internal naming
  • Reduced attack surface

Advanced DNS + CDN Interaction Patterns

DNS and CDNs work together in increasingly sophisticated ways.


Real-Time Traffic Steering

Modern DNS systems integrate:

  • Latency measurements
  • Regional health checks
  • Capacity signals

DNS responses adapt based on:

  • User location
  • Network congestion
  • Backend availability

This happens before any content is fetched.


Failover and Disaster Recovery

DNS enables:

  • Regional failover
  • Traffic draining
  • Disaster recovery routing

When a data center fails:

  • DNS redirects new traffic
  • Existing connections may degrade gracefully

DNS is the first lever in large-scale incident response.


Multi-CDN Strategies

Some organizations use:

  • Multiple CDNs
  • DNS-based traffic splitting
  • Performance-based routing

This reduces:

  • Vendor lock-in
  • Outage impact
  • Regional performance variance

DNS becomes a meta-load-balancer.

DNS Observability and Monitoring

Because DNS issues are invisible until they’re catastrophic, monitoring is essential.

Key signals include:

  • Query latency
  • Error rates
  • NXDOMAIN spikes
  • TTL behavior
  • Resolver diversity

Modern systems treat DNS as critical infrastructure, not plumbing.


DNS and Regulation

DNS increasingly intersects with policy.

Examples:

  • Domain takedowns
  • Government-mandated blocking
  • ISP-level filtering
  • Jurisdictional control

Because DNS is upstream of content, it is a powerful control point.

This raises questions about:

  • Censorship
  • Neutrality
  • Governance

Why DNS Is Hard to Replace

Many attempts have been made to “improve” DNS.

They fail because DNS is:

  • Deeply embedded
  • Backward compatible
  • Globally coordinated
  • Simple at its core

Any replacement must:

  • Interoperate with DNS
  • Migrate gradually
  • Preserve reliability

So far, nothing has met those constraints.


What Is DNS and How It Works Common DNS Myths (Debunked)

Myth: DNS is centralized
Reality: It is distributed by design.

Myth: DNS just maps names to IPs
Reality: It’s a control layer for traffic, performance, and availability.

Myth: DNS changes are instant
Reality: Caching is necessary for scale.

Myth: DNS is simple
Reality: The concept is simple; the system is not.


Mental Models for Mastering DNS

To truly understand DNS, keep these models in mind:

  1. DNS is a hierarchy of responsibility
  2. Caching is the reason DNS works at scale
  3. DNS answers “where,” not “what”
  4. DNS failures amplify globally
  5. DNS is both infrastructure and policy

These models help explain both behavior and failure.


Frequently Asked Questions About What Is DNS and How It Works

Can DNS be encrypted completely?
Queries can be encrypted in transit, but destination intent is still revealed eventually.

Why does DNS still use UDP?
Because it’s fast, simple, and sufficient for most queries.

Is DNSSEC widely used?
Adoption is growing, but uneven due to operational complexity.

Who controls the root DNS servers?
They are operated by multiple independent organizations under shared governance.


Final System-Level Synthesis

DNS works because it embraces a few powerful ideas:

  • Hierarchy instead of centralization
  • Caching instead of real-time coordination
  • Delegation instead of ownership
  • Redundancy instead of perfection

Every DNS query is a small act of global cooperation.

That cooperation scales to:

  • Billions of users
  • Trillions of queries
  • Constant change
  • Frequent failure

And yet, it mostly just works.


Conclusion: What DNS Really Is

DNS is often described as the internet’s phone book.

In reality, it is:

  • A global coordination system
  • A performance accelerator
  • A security boundary
  • A policy lever
  • A hidden dependency for everything online

Every website visit begins with DNS.
Every outage reminds us how much depends on it.

Understanding what DNS is and how it works reveals not just how the internet finds things—but how the internet holds itself together.

How YouTube Recommendations Work: A Deep, Practical Breakdown of the YouTube Algorithm

How YouTube Recommendations Work and Why YouTube Recommendations Deserve a Full Breakdown

Understanding how YouTube recommendations work is not optional if you care about visibility, influence, or digital media literacy.

YouTube is no longer a simple video-hosting platform. It is one of the largest personalization engines ever built, shaping what billions of people watch, learn, and believe every day.

More than 70% of watch time on YouTube comes from recommendations, not search. That single fact changes everything.

This article explains YouTube’s recommendation system from the inside out — not from rumors, shortcuts, or outdated advice — but from how large-scale recommendation systems actually function.

How YouTube Recommendations Work: What the YouTube Recommendation System Is Actually Optimizing For

A common misconception is that YouTube optimizes for:

  • Views
  • Clicks
  • Virality

It does not.

At a system level, YouTube optimizes for:

Long-term viewer satisfaction across sessions

This means the system evaluates not just what you watch, but:

  • How long you stay
  • Whether you return tomorrow
  • Whether recommendations improve your experience over time

This framing explains why many “viral” videos fail to sustain distribution.


How YouTube Recommendations Work: Where YouTube Recommendations Appear

Recommendations power nearly every surface on YouTube:

  • Home feed
  • Suggested videos (Up Next)
  • Autoplay
  • End screens
  • Notifications (partially)
  • Shorts feed

Each surface uses different ranking models, but they share the same underlying logic and data sources.

If you’re interested in how short-form recommendation differs, see our breakdown of how TikTok’s For You algorithm works , where content velocity and rapid feedback loops play a larger role.

The Two-Stage Architecture Behind YouTube Recommendations

YouTube does not rank all videos at once. That would be computationally impossible.

Instead, it uses a two-stage architecture.


How YouTube Recommendations Work Stage 1: Candidate Generation

Candidate generation answers one question:

“Which videos are even worth considering for this user right now?”

From billions of videos, YouTube narrows the pool to hundreds or thousands.

Candidate sources include:

  • Watch history similarity
  • Previously watched channels
  • Topic-based similarity
  • Popular content among similar users
  • Fresh uploads
  • Shorts exploration pools

This stage prioritizes speed over precision.


How YouTube Recommendations Work Stage 2: Ranking

Ranking answers a different question:

“In what order should these videos be shown to maximize satisfaction?”

Each candidate video is scored using machine learning models that estimate:

  • Probability of watching
  • Expected watch time
  • Likelihood of satisfaction
  • Risk of dissatisfaction
  • Session continuation value

The final feed is personalized per user, per moment.

How YouTube Recommendations Work: The Most Important Signals in YouTube Recommendations (Explained Properly)

There is no single “magic metric.”

YouTube combines dozens of signals, weighted differently depending on context.


Watch Time (With Nuance)

Watch time matters — but not in isolation.

YouTube evaluates:

  • Watch time relative to video length
  • Watch time compared to similar videos
  • Whether viewers keep watching afterward

A short video with high completion can outperform a longer one.


Session-Level Value

One of YouTube’s most important but least discussed concepts is session value.

The system tracks:

  • Does this video extend a session?
  • Does it end a session?
  • Does it lead to further satisfaction?

Videos that keep users on YouTube happily are rewarded.


Viewer Satisfaction Signals

YouTube explicitly measures satisfaction using:

  • Likes and dislikes
  • Viewer surveys
  • “Not interested” actions
  • Long-term return behavior

This is how YouTube counteracts pure clickbait.


Engagement Signals (Secondary but Reinforcing)

  • Comments
  • Shares
  • Subscriptions gained
  • Playlist additions

Engagement supports distribution, but only if watch behavior is strong.


How YouTube Recommendations Work Personalization: Why There Is No Single YouTube Algorithm

There is no universal YouTube feed.

Each user has:

  • A unique watch history
  • Individual interest embeddings
  • Different tolerance for novelty
  • Different satisfaction thresholds

The same video can:

  • Explode for one audience
  • Be invisible to another

Creators often misinterpret this as randomness. It is not.


How YouTube Recommendations Work: Early Feedback Loops and the “First Audience” Effect

Every video begins with a small test audience.

YouTube observes:

  • Click behavior
  • Watch depth
  • Satisfaction indicators

If the first audience responds positively, the system expands distribution to similar viewers.

If not, distribution slows — often permanently.

This makes audience alignment more important than broad appeal.

How YouTube Recommendations Work: Why YouTube Recommendations Change Over Time

Creators often say:

“The algorithm changed.”

Most of the time, what actually changed is:

  • Viewer expectations
  • Competing content
  • Topic saturation
  • Seasonal interest
  • Relative performance

YouTube’s models update constantly, but stability comes from consistent satisfaction, not tactics.


How YouTube Recommendations Work: Short-Term Spikes vs Long-Term Distribution

YouTube distinguishes between:

  • Initial performance
  • Sustained performance

Videos that:

  • Age well
  • Maintain relevance
  • Continue satisfying viewers

Can resurface months or years later.

This is why evergreen content matters.

How YouTube Recommendations Work: Long-Form Videos vs Shorts: Two Recommendation Systems Under One Roof

Although both appear on the same platform, long-form videos and Shorts are governed by different recommendation dynamics.

They share infrastructure, but not incentives.


Long-Form Video Recommendations

Long-form recommendations prioritize:

  • Session continuation
  • Sustained watch time
  • Viewer satisfaction across multiple videos
  • Return visits over days and weeks

The system asks:

“Does this video lead to a better overall viewing session?”

This explains why long-form videos can grow slowly and remain relevant for years.


Shorts Recommendations

Shorts operate on compressed feedback loops.

Key characteristics:

  • Extremely fast signal collection
  • Heavy reliance on completion rate
  • Rapid exploration of new creators
  • Less dependence on prior subscriptions

Shorts are optimized for immediate engagement, not long-term narrative arcs.

This is why Shorts can explode quickly — and disappear just as fast.

Why Shorts Success Doesn’t Always Transfer to Long-Form

Creators often assume Shorts success will boost long-form distribution. Sometimes it does — often it doesn’t.

Reasons include:

  • Different audience intent
  • Different satisfaction metrics
  • Different consumption patterns
  • Weak cross-format embeddings

In short: the system treats Shorts viewers and long-form viewers as different behavioral contexts.


How YouTube Recommendations Work: User Modeling on YouTube: How Viewers Are Represented

YouTube does not store users as simple profiles.

Instead, it uses dynamic user representations that evolve continuously.


Interest Embeddings

Each user is represented by multiple embeddings that encode:

  • Topic interests
  • Format preferences
  • Engagement intensity
  • Temporal behavior patterns

These embeddings update after nearly every interaction.


Why Small Actions Matter

Short interactions can disproportionately affect recommendations:

  • Skipping a video quickly
  • Watching one video twice
  • Ending a session early

These signals help the system infer what not to show as much as what to show.


Item Modeling: How Videos Are Understood

Videos are also represented as embeddings.

These representations incorporate:

  • Visual content
  • Audio features
  • Text metadata
  • Early viewer behavior
  • Audience retention patterns

The system does not “understand” meaning — it understands correlations.

How YouTube Recommendations Work: Exploration vs Exploitation on YouTube

YouTube constantly balances:

  • Exploitation (showing known favorites)
  • Exploration (testing new content)

How Exploration Works in Practice

Exploration appears as:

  • New channels in your feed
  • Slight topic deviations
  • Fresh uploads
  • Experimental Shorts

These tests are deliberate, not random.

If exploration content performs well, it becomes part of the user’s stable recommendation profile.


Why Over-Exploration Feels “Off”

If exploration overwhelms relevance:

  • Users feel confused
  • Satisfaction drops
  • Session length decreases

The system quickly corrects by reverting to safer recommendations.


The First 48 Hours: Early Distribution Mechanics

The first 24–48 hours of a video’s life are critical.

During this phase, YouTube evaluates:

  • Initial click behavior
  • Early watch depth
  • Satisfaction signals
  • Audience match quality

However, early performance is relative, not absolute.

A video is judged against:

  • Similar content
  • Similar channels
  • Similar audience sizes

This is why small channels can still succeed.


Why Videos Sometimes “Flatline”

A flatline usually means:

  • The test audience did not engage deeply
  • Retention dropped compared to peers
  • The video ended sessions
  • Negative feedback accumulated

This is not punishment — it is resource reallocation.


How YouTube Recommendations Work: Monetization-Aware Ranking (Without Myths)

YouTube does not rank purely for ads, but monetization constraints do exist.

Factors include:

  • Advertiser suitability
  • Content safety
  • Viewer trust
  • Brand risk

Videos that violate guidelines may still be recommended — but with reduced reach.


Trust, Safety, and Policy Constraints

Recommendation systems operate within hard boundaries.

Constraints include:

  • Misinformation policies
  • Harmful content detection
  • Age-appropriateness
  • Legal requirements

These constraints override pure engagement optimization.

How YouTube Recommendations Work: Why “Shadowbanning” Is the Wrong Mental Model

Creators often interpret drops in reach as shadowbans.

In practice:

  • Distribution is performance-based
  • Audience interest shifts
  • Competition increases
  • Relative metrics change

There is no need for hidden suppression when automated ranking already reallocates attention efficiently.


Common Creator Failure Modes

Understanding failure modes helps avoid them.


Failure Mode 1: Misaligned Thumbnails

High click, low watch time = negative signal.


Failure Mode 2: Audience Drift

Sudden topic shifts confuse user embeddings.


Failure Mode 3: Chasing Trends Blindly

Trend saturation lowers relative performance.


Failure Mode 4: Optimizing for One Metric

Watch time without satisfaction leads to decay.


Why Consistency Actually Matters

Consistency helps the system:

  • Predict audience match
  • Build stable embeddings
  • Reduce exploration risk

This does not mean repeating content — it means maintaining audience clarity.


Why Some Old Videos Suddenly Resurface

Resurfacing occurs when:

  • Topic relevance returns
  • New audience clusters emerge
  • Seasonal interest spikes
  • Model updates re-rank content

Evergreen videos are stored, not forgotten.


Advanced Myths (Debunked)

Myth: Uploading daily boosts recommendations
Reality: Viewer satisfaction dominates frequency

Myth: Deleting videos hurts the channel
Reality: Minimal impact unless patterns are extreme

Myth: External traffic hurts recommendations
Reality: Only if it reduces satisfaction


Mental Model: Think in Distributions, Not Decisions

The system does not “decide” a video’s fate.

It continuously updates probability distributions:

  • Who might like this?
  • How likely are they to watch?
  • What happens after?

This probabilistic framing explains all observed behavior.

How YouTube Measures “Success” Internally (Beyond Surface Metrics)

Creators see metrics like views, watch time, and click-through rate.
YouTube’s recommendation system sees something more abstract: expected value.

Instead of asking:

“Did this video do well?”

The system asks:

“How valuable was this video for this viewer compared to alternatives?”

This comparison-based framing explains many counterintuitive outcomes.


Relative Performance, Not Absolute Numbers

A common misunderstanding is assuming high numbers automatically mean success.

In reality, performance is judged relative to peers, such as:

  • Videos of similar length
  • Videos on similar topics
  • Videos shown to similar audiences
  • Videos from similar-sized channels

A video with:

  • 10,000 views can be a success
  • 1 million views can be a failure

It depends on what the system expected.


How YouTube Recommendations Work: Ranking Metrics as Trade-Offs, Not Targets

YouTube does not optimize one metric at a time.

It balances multiple competing objectives, including:

  • Watch time
  • Satisfaction
  • Retention
  • Diversity
  • Safety
  • Exploration

Improving one metric at the expense of others often backfires.


Why Click-Through Rate Alone Is Dangerous

High CTR with low watch depth signals:

  • Misleading packaging
  • Audience mismatch
  • Poor expectation setting

The system learns to trust watch behavior over clicks.


Why Watch Time Alone Isn’t Enough

High watch time with:

  • Session endings
  • Negative feedback
  • Viewer fatigue

Can still lose distribution.

This is why YouTube emphasizes long-term satisfaction.


Multi-Objective Optimization (Without the Math)

Internally, YouTube’s ranking models learn to trade off objectives.

Conceptually:

  • Each video has strengths and weaknesses
  • The system chooses acceptable compromises
  • No video maximizes everything

This is why:

  • Some videos are great for discovery
  • Others are great for retention
  • Others serve niche audiences

Different videos win in different contexts.


How YouTube Evaluates Creator Reliability

Beyond individual videos, YouTube builds models of creator reliability.

This does not mean favoritism.

It means estimating:

  • How predictable viewer satisfaction is
  • How often content meets expectations
  • How risky recommendations might be

Creators with consistent audience alignment are easier to recommend confidently.


Why Consistency Reduces Risk

From the system’s perspective:

  • Consistent creators reduce uncertainty
  • Reduced uncertainty improves ranking confidence
  • Confidence allows broader testing

This is why erratic pivots often reduce reach temporarily.


Channel-Level vs Video-Level Dynamics

A critical distinction many creators miss:

  • Videos compete against videos
  • Channels build reputations over time

A single underperforming video does not “kill” a channel.
But repeated misalignment increases system uncertainty.


Why Some Channels Plateau

Plateaus often occur when:

  • Audience size stabilizes
  • Topic saturation increases
  • Marginal viewers are less interested
  • Competition intensifies

This is not punishment — it’s market equilibrium.

Breaking plateaus usually requires:

  • New audience segments
  • Format innovation
  • Deeper value, not broader appeal

Explaining “Algorithm Favoritism” Without Conspiracies

When some creators consistently perform well, it can look like favoritism.

What’s actually happening:

  • The system has high confidence in audience satisfaction
  • Distribution risk is low
  • Performance variance is predictable

This is statistical trust, not preference.


How YouTube Handles Uncertainty

Uncertainty is expensive.

The system must decide:

  • Should this video be tested further?
  • Is the risk worth the potential reward?
  • Will this harm user trust?

When uncertainty is high, exploration is conservative.

Long-Term Channel Growth as a Systems Problem

Successful channels align with the system rather than fighting it.

Long-term growth emerges from:

  • Stable audience signals
  • Clear value proposition
  • Predictable satisfaction
  • Periodic innovation

Growth is not linear — it is phase-based.


Growth Phase 1: Audience Discovery

  • Heavy exploration
  • High volatility
  • Inconsistent distribution

Growth Phase 2: Audience Fit

  • Stabilizing metrics
  • Improving retention
  • Narrowing audience definition

Growth Phase 3: Optimization

  • Predictable performance
  • Slower growth
  • Strong loyalty

Growth Phase 4: Expansion or Decline

  • Expand thoughtfully → new growth curve
  • Stay static → plateau
  • Misalign → decline

Understanding these phases prevents misinterpretation of normal cycles.


Why “Going Viral” Is Not a Strategy

Virality is a side effect, not a plan.

Viral spikes often:

  • Attract misaligned viewers
  • Damage long-term metrics
  • Increase churn
  • Reduce system confidence

Sustainable growth comes from repeat satisfaction, not spikes.


Audience Matching: The Most Underrated Factor

The system prioritizes who sees a video more than how many see it.

A perfectly matched small audience:

  • Outperforms a poorly matched large one
  • Produces stronger feedback loops
  • Enables broader distribution later

This is why niche clarity often beats broad appeal.


Why Metadata Matters Less Than People Think

Titles, thumbnails, and descriptions help:

  • Set expectations
  • Enable discovery
  • Improve early clicks

But they cannot override:

  • Poor watch behavior
  • Audience mismatch
  • Low satisfaction

Metadata opens the door — behavior decides what happens next.


Advanced Failure Case: The “Good Metrics, Bad Growth” Trap

Some creators see:

  • High watch time
  • Good CTR
  • Strong engagement

Yet growth stalls.

Common reasons:

  • Audience too narrow
  • Limited scalability
  • Low session continuation
  • High redundancy

The system sees no reason to expand further.


Strategic Takeaways for Advanced Creators

Think in terms of:

  • Audience alignment, not hacks
  • Systems, not switches
  • Probabilities, not promises
  • Long-term trust, not short-term spikes

Creators who understand the system stop asking:

“What does the algorithm want?”

And start asking:

“What experience am I consistently delivering?”

Shorts ↔ Long-Form Crossover: What Actually Transfers (and What Doesn’t)

One of the most misunderstood topics on YouTube is whether success in Shorts helps long-form videos.

The answer is nuanced.


What Transfers Successfully

Some signals do carry over:

  • Channel-level recognition
  • Brand familiarity
  • Viewer curiosity
  • Creator reliability (weakly)

If Shorts viewers intentionally click into long-form and watch deeply, positive transfer occurs.

What Does Not Transfer Automatically

Most Shorts signals do not translate cleanly:

  • Completion rate
  • Swipe behavior
  • Rapid feedback loops
  • Passive consumption patterns

Shorts success alone does not redefine long-form audience embeddings.


Why This Matters Strategically

Creators should treat Shorts as:

  • A discovery surface
  • A testing ground for ideas
  • A brand awareness channel

Not as a shortcut to long-form growth.


Safe Experimentation Without Damaging Your Channel

Experimentation is necessary — but reckless experimentation confuses the system.


Why Sudden Pivots Are Risky

Sudden changes can:

  • Disrupt audience embeddings
  • Increase uncertainty
  • Reduce recommendation confidence

The system doesn’t “punish” — it hesitates.


How to Experiment Safely

Best practices:

  • Experiment within adjacent topics
  • Use secondary formats or series
  • Gradually shift audience expectations
  • Watch who responds, not just how many

Think evolution, not reinvention.


Why Recommendation Systems Fail Gracefully (Most of the Time)

Despite their power, YouTube’s recommendation systems are designed to fail safely.


Graceful Failure Mechanisms

These include:

  • Limited initial testing
  • Gradual rollout
  • Performance thresholds
  • Human oversight
  • Safety constraints

This prevents catastrophic amplification of low-quality or harmful content.


Why This Protects Creators Too

Graceful failure means:

  • One bad video doesn’t end a channel
  • Experiments don’t permanently define you
  • Recovery is possible with alignment

The system is cautious by design.

The Most Accurate Mental Model of the YouTube Algorithm

After everything covered in this guide, the most accurate mental model is this:

YouTube is a large-scale prediction system optimizing for long-term viewer satisfaction under uncertainty and constraints.

It is not:

  • A rulebook
  • A scorecard
  • A judge
  • An enemy

It is a probabilistic engine making trade-offs at scale.


Why Creators Who “Crack the Algorithm” Often Burn Out

Creators chasing the algorithm tend to:

  • Over-optimize
  • Lose authenticity
  • Chase metrics over meaning
  • Confuse short-term gains with strategy

Creators who align with viewers:

  • Grow slower
  • Grow steadier
  • Last longer

Longevity is the real optimization.


System Literacy vs Algorithm Anxiety

Most creator frustration comes from misattribution.

Normal phenomena mistaken for algorithmic punishment:

  • Audience fatigue
  • Topic saturation
  • Competition growth
  • Platform maturity

Understanding the system replaces anxiety with clarity.


What YouTube Recommendations Cannot Do

Despite their sophistication, recommendation systems cannot:

  • Read intent
  • Understand truth
  • Judge creativity
  • Guarantee success
  • Replace human taste

They respond to patterns — nothing more.


Extended Expert FAQs

Does uploading time affect recommendations?
Only marginally; relevance and satisfaction dominate.

Do comments boost ranking?
Only if they correlate with positive watch behavior.

Does deleting underperforming videos help?
Rarely; focus on future alignment instead.

Can channels recover from long declines?
Yes — but recovery requires genuine audience realignment.

Are smaller creators disadvantaged?
No. Relative performance matters more than size.

Is YouTube getting harder or just more competitive?
More competitive — not more hostile.


How This Support Article Complements the Pillar

This article answers the “how does this work in practice?” question.

The pillar article explains:

  • Recommendation systems as a class
  • Core mechanics across platforms
  • System-level trade-offs

This support article:

  • Applies those mechanics concretely to YouTube
  • Explains creator-facing consequences
  • Provides actionable mental models

Together, they form a coherent knowledge base.


Final Synthesis: How YouTube Recommendations Really Work

YouTube recommendations are not mysterious forces operating behind a curtain.

They are:

  • Data-driven
  • Behavior-based
  • Continuously adapting
  • Constraint-aware
  • Long-term oriented

Creators who succeed are not those who “game the system,”
but those who consistently deliver value to a clearly defined audience.

When audience satisfaction aligns with system incentives, growth becomes a byproduct — not a chase.

Conclusion

Understanding how YouTube recommendations work does not give you control.

It gives you context.

And with context:

  • You make better creative decisions
  • You interpret metrics correctly
  • You stop chasing myths
  • You build sustainably

That is the real advantage.

Streaming platforms often combine recommendation systems with subscription paywalls that control access to premium content. These access models are explained in how paywalls work .

How Recommendation Algorithms Work: The Complete, Powerful Guide to Modern Personalization

How Recommendation Algorithms Work: Recommendation algorithms quietly shape the modern digital world.

Every time you watch a video, scroll a feed, buy a product, or listen to music, recommendation algorithms are working behind the scenes to decide what you see next.

At their core, recommendation algorithms are systems designed to predict what a user is most likely to engage with. These predictions are based on data, patterns, and probabilities rather than human judgment. While the concept sounds simple, the systems behind it are some of the most complex technologies ever built.

Today, recommendation algorithms power:

  • Streaming platforms
  • Social media feeds
  • E-commerce product suggestions
  • News personalization
  • Online learning platforms

Without recommendation algorithms, users would be overwhelmed by choice. With them, content becomes curated, ranked, and personalized.

Why Recommendation Systems Matter Today

The internet produces more content than any human could possibly consume. Millions of videos, posts, products, and articles are created every day. Recommendation systems solve this problem by acting as filters and guides.

From a business perspective, recommendation algorithms:

  • Increase user engagement
  • Extend session time
  • Improve retention
  • Drive revenue

From a user perspective, they:

  • Reduce cognitive overload
  • Improve relevance
  • Save time
  • Create personalized experiences

This dual benefit is why recommendation algorithms are considered one of the most valuable technologies in modern computing.


How Recommendation Algorithms Work: The Core Goal of Recommendation Algorithms

Despite their complexity, all recommendation algorithms share a single core objective:

Deliver the most relevant item to the right user at the right time.

To achieve this, systems must answer three questions:

  1. Who is the user?
  2. What items are available?
  3. Which item best matches the user’s current intent?

Answering these questions requires ranking logic, personalization systems, and continuous feedback.


Types of Recommendation Systems

Collaborative Filtering

Collaborative filtering works by finding patterns among users. If two users behave similarly, the system assumes they will like similar items.

Key idea:

  • Users who liked X also liked Y

Strengths:

  • No need to understand the content itself
  • Learns from collective behavior

Weaknesses:

  • Struggles with new users and new items
  • Can reinforce popularity bias

Content-Based Filtering

Content-based filtering focuses on the attributes of items rather than other users. If a user likes certain features, the system recommends items with similar features.

Key idea:

  • You liked items with these characteristics before

Strengths:

  • Strong personalization
  • Works well for niche interests

Weaknesses:

  • Limited discovery
  • Can create filter bubbles

How Recommendation Algorithms Work: Hybrid Recommendation Systems

Most modern platforms combine multiple approaches. Hybrid systems blend collaborative filtering, content-based filtering, and ranking logic to balance relevance, discovery, and diversity.

Data Collection in Recommendation Systems

Recommendation algorithms rely on data. Without data, there is no personalization.

Explicit Feedback

Explicit feedback is directly provided by users:

  • Ratings
  • Likes
  • Dislikes
  • Reviews

This data is valuable but limited because most users do not actively provide feedback.


Implicit Feedback

Implicit feedback is inferred from behavior:

  • Watch time
  • Clicks
  • Scroll depth
  • Purchase history
  • Skips

Modern recommendation systems rely heavily on implicit feedback because it is abundant and continuous.


Understanding Ranking Logic

Ranking logic determines the order in which items are shown. This is one of the most critical components of recommendation algorithms.

Rather than choosing a single item, systems:

  1. Generate a large candidate set
  2. Score each candidate
  3. Rank items based on predicted relevance

Scoring Systems Explained

Each item receives a score based on:

  • Predicted engagement
  • User interest similarity
  • Freshness
  • Popularity
  • Context (time, device, location)

The highest-scoring items appear first.


Ranking vs Retrieval

  • Retrieval selects which items are eligible
  • Ranking decides the order

Both stages work together to deliver fast, relevant results.

How Recommendation Algorithms Work: Personalization Systems and User Modeling

Personalization systems attempt to model user preferences in mathematical form.

They answer questions like:

  • What topics does the user prefer?
  • How strong is that preference?
  • How stable is it over time?

User Profiles and Preferences

User profiles are dynamic and evolve constantly. Every interaction updates the system’s understanding of the user.


User Embeddings Explained

User embeddings are numerical representations of users in multi-dimensional space. They allow algorithms to compare users and items mathematically.

Users with similar embeddings are assumed to have similar interests.

Feedback Loops in Recommendation Systems

Feedback loops occur when recommendations influence user behavior, which then feeds back into the system.

This can lead to:

  • Rapid trend amplification
  • Echo chambers
  • Unintended bias

Positive and Negative Feedback Loops

  • Positive loops reinforce engagement
  • Negative loops suppress diversity

Managing feedback loops is one of the hardest challenges in recommendation system design.


How Recommendation Algorithms Work: Why Recommendations Change Over Time

Recommendations evolve because:

  • User interests shift
  • Content supply changes
  • System models update
  • Feedback accumulates

This dynamic behavior keeps systems adaptive but unpredictable.

Platform Case Studies (Preview)

Modern platforms such as YouTube, TikTok, and Netflix use large-scale hybrid systems that combine all of the concepts discussed so far.

(These will be explored in dedicated depth sections later in the article.)

How Recommendation Algorithms Work: Frequently Asked Questions (Preview)

Q1: Are recommendation algorithms the same as AI?
No, but many use machine learning, which is a subset of AI.

Q2: Do recommendation systems track users?
They track behavior patterns, often anonymously.

Q3: Can recommendation algorithms be wrong?
Yes, predictions are probabilistic, not certain.

Q4: Why do recommendations feel repetitive?
This is often caused by feedback loops.

Q5: Can users control recommendations?
Some platforms offer limited controls.

Q6: Are recommendation algorithms biased?
Bias can emerge from data and design choices.

How Recommendation Algorithms Work: Exploration vs Exploitation in Recommendation Algorithms

One of the most important — and least visible — challenges in recommendation algorithms is balancing exploration and exploitation.

  • Exploitation means showing content the system is confident the user will like.
  • Exploration means showing new or uncertain content to learn more about the user.

If a system only exploits, it becomes repetitive.
If it only explores, it feels random.

Modern recommendation algorithms constantly optimize this balance.

Why Exploration Is Necessary

Exploration allows systems to:

  • Discover new user interests
  • Avoid stale recommendations
  • Prevent overfitting to past behavior
  • Introduce new creators or products

Without exploration, systems would never adapt when a user’s preferences change.

How Exploration Is Implemented

Common exploration techniques include:

  • Randomized sampling
  • Confidence-based ranking
  • Time-based content injection
  • Diversity constraints

Many platforms quietly inject exploratory items into feeds to test reactions.

The Cold Start Problem

The cold start problem occurs when a recommendation system lacks sufficient data.

There are two major cold start scenarios:

  1. New users
  2. New items

In both cases, the system has limited historical information.


Cold Start for New Users

When a user joins a platform, the system knows almost nothing about them.

Common solutions include:

  • Popular content defaults
  • Onboarding questionnaires
  • Contextual signals (location, device, time)
  • Rapid exploration

This is why early recommendations often feel generic.


Cold Start for New Items

New content has no interaction data.

Platforms handle this by:

  • Boosting visibility temporarily
  • Using content similarity
  • Leveraging creator history
  • Applying exploration logic

This ensures new items have a chance to be discovered.


How Recommendation Algorithms Work: Bias, Fairness, and Ethics in Recommendation Systems

Recommendation algorithms are not neutral. They reflect the data they are trained on and the objectives they optimize.

Common Sources of Bias

Bias can enter systems through:

  • Historical data patterns
  • Popularity amplification
  • Feedback loops
  • Optimization goals (e.g., watch time)

These biases can disadvantage certain creators, topics, or user groups.


Filter Bubbles and Echo Chambers

When systems over-personalize, users may see only content that reinforces existing beliefs.

This can:

  • Limit exposure to diverse perspectives
  • Increase polarization
  • Reduce discovery

Many platforms now actively design against extreme filter bubbles.


Ethical Design Considerations

Responsible recommendation systems consider:

  • Diversity and fairness
  • Transparency
  • User control
  • Long-term well-being

Ethics is becoming a core part of system design, not an afterthought.


How Recommendation Algorithms Work:Real-World Recommendation System Architecture

Large-scale recommendation systems are distributed, layered, and highly optimized.

A typical architecture includes:

  1. Data ingestion
  2. Feature extraction
  3. Candidate generation
  4. Ranking models
  5. Feedback collection
  6. Continuous retraining

Each layer operates at massive scale.

Candidate Generation: The First Filtering Layer

Candidate generation narrows millions of items down to a manageable set.

Techniques include:

  • Collaborative filtering retrieval
  • Content similarity search
  • Embedding-based nearest neighbors
  • Popularity-based heuristics

This step prioritizes speed over precision.


Ranking Models: Precision at Scale

Ranking models evaluate candidates in detail.

They consider:

  • User-item similarity
  • Engagement predictions
  • Contextual signals
  • Business rules

Ranking is where most machine learning complexity lives.


Evaluation Metrics for Recommendation Algorithms

You cannot improve what you cannot measure.

Offline Metrics

Used during model training:

  • Precision
  • Recall
  • Mean Average Precision
  • NDCG

These evaluate predictive accuracy.


Online Metrics

Measured in live systems:

  • Click-through rate
  • Watch time
  • Session length
  • Retention

Online metrics reflect real user behavior.


Platform Deep Dive: YouTube Recommendation System

The recommendation system used by YouTube is one of the most studied in the world.

Its primary optimization goal is long-term viewer satisfaction, not just clicks.

Key signals include:

  • Watch time
  • Engagement actions
  • Viewer surveys
  • Session duration

YouTube uses deep neural networks to rank videos at scale.


Platform Deep Dive: TikTok For You Page

The TikTok For You feed is built for rapid personalization.

Notable characteristics:

  • Extremely fast feedback loops
  • Heavy reliance on implicit signals
  • Strong exploration early on
  • Fine-grained content embeddings

This allows TikTok to understand preferences within minutes.


Platform Deep Dive: Netflix Recommendations

Netflix focuses on taste-based personalization rather than social trends.

Key features:

  • Multiple recommendation rows
  • A/B tested artwork
  • Long-term preference modeling
  • Strong collaborative filtering foundations

Netflix optimizes for sustained satisfaction, not virality.


Why Recommendation Algorithms Feel “Psychological”

Recommendation systems often feel like they “know” users.

This illusion comes from:

  • Pattern recognition at scale
  • Probabilistic prediction
  • Rapid feedback cycles

The system does not understand users — it predicts behavior based on similarity and history.


The Future of Recommendation Algorithms

The next generation of recommendation systems will focus on:

  • Multi-objective optimization
  • User well-being metrics
  • Greater transparency
  • Decentralized personalization
  • On-device recommendation models

Regulation and public awareness will also shape future designs.


Frequently Asked Questions

What data do recommendation algorithms use most?
Implicit behavioral data is the most valuable.

Can users reset recommendations?
Some platforms allow partial resets.

Are recommendation algorithms manipulative?
They optimize for goals defined by designers.

Why do recommendations sometimes feel wrong?
Predictions are probabilistic, not deterministic.

Do smaller platforms use similar systems?
Yes, but at smaller scale and complexity.

Will recommendation systems replace search?
They already complement and sometimes outperform it.


Conclusion: Understanding Recommendation Algorithms

Recommendation algorithms are not magic. They are structured systems built on data, mathematics, and feedback.

Understanding how recommendation algorithms work empowers users, creators, and businesses to:

  • Navigate platforms more effectively
  • Design better systems
  • Recognize unintended effects
  • Make informed decisions

As these systems continue to shape digital life, literacy about them becomes essential.

Mathematical Intuition Behind Recommendation Algorithms (Without the Math Overload)

Although recommendation algorithms rely heavily on mathematics, most systems can be understood intuitively without equations.

At a high level, recommendation algorithms are prediction engines. They attempt to estimate the probability that a user will engage with an item.

Instead of asking:

“Will the user like this?”

The system asks:

“How likely is this user to interact with this item compared to all other items?”

This shift from certainty to probability is fundamental.


Similarity as Distance

Most recommendation systems rely on the idea of distance.

  • Users and items are represented as points
  • Similar users are closer together
  • Relevant items are closer to the user

The closer an item is to a user’s representation, the higher it ranks.

This geometric intuition explains why recommendations can adapt smoothly rather than changing abruptly.

A Deeper Look at Embeddings

Embeddings are one of the most important breakthroughs in modern recommendation algorithms.

They convert complex information into numerical vectors that capture meaning, preference, and context.


What Embeddings Actually Represent

An embedding is not a label or a category.
It is a compressed summary of behavior and attributes.

For users, embeddings may encode:

  • Topic interests
  • Engagement intensity
  • Content consumption patterns
  • Temporal preferences

For items, embeddings may encode:

  • Content themes
  • Style
  • Format
  • Audience response patterns

The system never “knows” what these dimensions mean — it only learns how they relate.


Why Embeddings Are So Powerful

Embeddings allow systems to:

  • Generalize beyond seen data
  • Handle sparse interactions
  • Compare users and items efficiently
  • Scale to billions of entities

This is why embedding-based systems dominate modern personalization.


Short-Term vs Long-Term Optimization

One of the hardest problems in recommendation system design is deciding what to optimize for.


Short-Term Optimization

Short-term metrics include:

  • Clicks
  • Likes
  • Watch time
  • Immediate engagement

Optimizing for short-term signals can boost usage quickly but may degrade long-term satisfaction.


Long-Term Optimization

Long-term objectives include:

  • Retention
  • Habit formation
  • User trust
  • Sustainable engagement

Balancing short-term and long-term goals requires sophisticated modeling and experimentation.

Many platforms now explicitly penalize content that boosts engagement but harms long-term satisfaction.


Unintended Effects of Recommendation Algorithms

Even well-designed systems can produce unexpected outcomes.


Popularity Amplification

Popular content often becomes more popular simply because it is recommended more.

This can:

  • Crowd out niche content
  • Reduce creator diversity
  • Create winner-take-all dynamics

Platforms often counter this with diversity constraints.


Behavior Shaping

Recommendation algorithms don’t just reflect preferences — they shape them.

Repeated exposure can:

  • Influence tastes
  • Normalize behaviors
  • Shift cultural trends

This influence is why recommendation systems carry social responsibility.

Regulation, Transparency, and User Control

As recommendation algorithms grow more influential, regulation has become inevitable.


Transparency Challenges

True transparency is difficult because:

  • Models are complex
  • Decisions are probabilistic
  • Explanations may be misleading

Many platforms instead offer interpretable signals, such as:

  • “Recommended because you watched…”
  • Interest controls
  • Topic preferences

User Control Mechanisms

Common controls include:

  • Hiding content
  • Resetting recommendations
  • Choosing interest categories
  • Following or unfollowing signals

These controls allow partial influence without exposing full system complexity.


How Recommendation Algorithms Are Trained

Training a recommendation system is not a one-time event.

It is a continuous cycle:

  1. Collect interaction data
  2. Train models
  3. Deploy models
  4. Measure outcomes
  5. Update objectives
  6. Repeat

This loop can run daily or even continuously.


Offline Training vs Online Learning

  • Offline training uses historical data
  • Online learning adapts models in real time

Most large platforms use a hybrid approach.


A/B Testing in Recommendation Systems

Almost every change in a recommendation system is tested.

A/B testing allows teams to:

  • Compare models
  • Measure real user impact
  • Detect unintended consequences

Even small ranking changes can produce massive behavioral shifts.


Why Perfect Recommendations Are Impossible

There is no such thing as a perfect recommendation system.

Reasons include:

  • Human preferences are unstable
  • Context changes constantly
  • Data is incomplete
  • Objectives conflict

The goal is not perfection, but continuous improvement.


Advanced Feedback Loop Dynamics

Earlier, we discussed feedback loops conceptually. At scale, they become more complex.


Multi-Level Feedback Loops

Feedback loops can exist:

  • Within a user
  • Across user groups
  • Across time
  • Across content ecosystems

Breaking harmful loops requires system-wide intervention, not local fixes.


Design Principles for Responsible Recommendation Systems

Modern systems increasingly follow guiding principles:

  • Diversity over monoculture
  • Long-term trust over short-term clicks
  • User agency over manipulation
  • Robustness over optimization extremes

These principles shape the future of personalization.


Extended Frequently Asked Questions

Can recommendation algorithms predict emotions?
They infer behavior patterns, not emotions directly.

Why does the same content perform differently for different users?
Because ranking is personalized per user context.

Are recommendations the same for everyone?
No, even “trending” content is ranked differently per user.

Do recommendation systems learn in real time?
Many systems partially adapt in real time.

Can recommendation algorithms be audited?
Auditing is difficult but increasingly explored.

Will regulation limit personalization?
It may change how systems balance transparency and performance.


Final Perspective: Why This Knowledge Matters

Understanding how recommendation algorithms work is no longer optional.

They shape:

  • Information access
  • Cultural trends
  • Economic opportunity
  • Public discourse

By understanding their mechanics, limitations, and incentives, users and creators gain clarity — and platforms gain accountability.

Collaborative Filtering: The Backbone of Recommendation Algorithms

Collaborative filtering is one of the earliest and most influential approaches in recommendation systems, and it remains foundational today.

The core idea is simple:

Users who behaved similarly in the past are likely to behave similarly in the future.

Rather than analyzing content itself, collaborative filtering relies on patterns of interaction.


User-Based Collaborative Filtering

User-based collaborative filtering focuses on similarities between users.

Process overview:

  1. Identify users with similar behavior
  2. Aggregate their preferences
  3. Recommend items liked by similar users

Strength:

  • Intuitive and explainable

Limitation:

  • Does not scale well with large user bases

Item-Based Collaborative Filtering

Item-based collaborative filtering flips the perspective.

Instead of comparing users, it compares items:

  • Items frequently consumed together are considered similar
  • Recommendations are generated based on item similarity

Strength:

  • More stable than user-based approaches
  • Scales better

This approach powered early versions of large e-commerce platforms.


Why Pure Collaborative Filtering Falls Short

Despite its power, collaborative filtering alone struggles with:

  • Cold start problems
  • Sparse data
  • Rapidly changing interests

This is why modern systems rarely use it in isolation.

Content-Based Filtering: Understanding Preferences Directly

Content-based filtering focuses on what items are, not who else liked them.

If a user consistently engages with certain attributes, the system recommends items with similar attributes.


Feature Engineering in Content-Based Systems

Content-based filtering depends heavily on features, such as:

  • Text keywords
  • Visual characteristics
  • Audio features
  • Metadata
  • Style and format

Machine learning models learn which features correlate with user engagement.


Strengths of Content-Based Filtering

  • Strong personalization
  • Works well for niche interests
  • Less dependent on other users

Weaknesses and Filter Bubbles

The biggest risk is over-specialization.

If the system only recommends similar content, users may never discover new interests. This can create filter bubbles even without social influence.


Hybrid Recommendation Systems: Why Real Platforms Combine Everything

Modern recommendation algorithms are hybrid by necessity.

They combine:

  • Collaborative filtering
  • Content-based filtering
  • Contextual signals
  • Ranking heuristics
  • Business rules

Each component compensates for the weaknesses of the others.


Why Hybrids Win

Hybrid systems:

  • Reduce cold start issues
  • Improve diversity
  • Increase robustness
  • Adapt better to change

This layered approach is now standard across major platforms.


Contextual Recommendation: Time, Place, and Situation

Context dramatically affects what users want.

The same user may prefer:

  • Short content during work breaks
  • Long-form content at night
  • Different topics depending on mood or season

Key Contextual Signals

Common contextual inputs include:

  • Time of day
  • Day of week
  • Device type
  • Location
  • Network conditions

Context-aware ranking improves relevance without changing user profiles.

Failure Cases in Recommendation Algorithms

No recommendation system is immune to failure.

Understanding failure modes is critical for responsible design.


Runaway Feedback Loops

When engagement metrics dominate, systems can amplify:

  • Sensational content
  • Extreme opinions
  • Addictive patterns

Unchecked loops can distort ecosystems rapidly.


Misaligned Objectives

If a system optimizes for the wrong metric, it will succeed at the wrong goal.

Examples:

  • Maximizing watch time at the expense of satisfaction
  • Boosting clicks without content quality
  • Prioritizing short-term growth over trust

Good systems align metrics with long-term value.


Data Drift and Model Decay

User behavior evolves.

If models are not retrained or monitored:

  • Predictions degrade
  • Recommendations feel stale
  • Bias increases

Continuous learning is essential.


Ranking Constraints and Business Rules

Not all ranking decisions are purely algorithmic.

Platforms impose constraints such as:

  • Content safety rules
  • Legal compliance
  • Diversity requirements
  • Sponsored content placement

These rules coexist with machine learning models.


Why Constraints Are Necessary

Without constraints:

  • Harmful content could spread
  • Minority creators could be suppressed
  • Legal risk increases

Constraints guide algorithms toward acceptable outcomes.


Discovery vs Relevance: A Constant Trade-Off

High relevance often conflicts with discovery.

  • Relevance favors known preferences
  • Discovery introduces novelty

Healthy systems intentionally sacrifice some relevance to:

  • Support creators
  • Encourage exploration
  • Prevent stagnation

This trade-off is a design choice, not a technical limitation.


How Recommendation Systems Handle Scale

At global scale, systems must operate under strict constraints.

Challenges include:

  • Latency (milliseconds matter)
  • Memory limits
  • Distributed computation
  • Fault tolerance

This is why recommendation systems are among the most complex distributed systems ever built.

Human-in-the-Loop Systems

Despite automation, humans still play a role.

Human input is used to:

  • Define objectives
  • Set constraints
  • Audit outcomes
  • Review edge cases

Fully autonomous recommendation systems remain unrealistic and undesirable.


Why Recommendation Algorithms Keep Changing

Users often ask why platforms “change their algorithm.”

In reality:

  • Models update
  • Objectives shift
  • Constraints evolve
  • Data changes

The system is never static.

Change is a feature, not a flaw.


Bridging This Pillar to the Support Articles

This pillar article serves as the foundation for deeper dives into:

  • Platform-specific systems
  • Filtering techniques
  • Embedding models
  • Feedback dynamics

Each support article expands one component without repeating the whole system.

Real-World Failures of Recommendation Algorithms (And What They Teach Us)

Recommendation algorithms are powerful, but history shows that power comes with risk. Studying failures reveals more than studying successes.


Failure Case 1: Over-Optimization for Engagement

When systems optimize aggressively for engagement metrics like clicks or watch time, unintended outcomes can emerge:

  • Sensationalism outperforms nuance
  • Extremes outperform moderation
  • Emotional triggers outperform accuracy

The lesson: Metrics shape reality. What you optimize for becomes what the system produces.


Failure Case 2: Creator Ecosystem Collapse

Some platforms have seen:

  • Sudden drops in reach for entire creator categories
  • Over-reliance on a small group of “winners”
  • Reduced diversity of content

These failures highlight the need for ecosystem-aware design, not just user-level optimization.


Failure Case 3: Trust Erosion

When recommendations feel manipulative or irrelevant, users disengage.

Trust failures occur when:

  • Systems change without explanation
  • Users feel powerless
  • Content quality declines

Once trust is lost, even accurate recommendations feel unwelcome.


How Recommendation Algorithms Work: Economic Impact of Recommendation Algorithms

Recommendation systems are not just technical tools — they are economic engines.

They determine:

  • Which creators succeed
  • Which products sell
  • Which ideas spread

This gives platforms enormous influence over attention and income distribution.


The Attention Economy Effect

In attention-driven ecosystems:

  • Visibility equals opportunity
  • Ranking equals revenue
  • Algorithms act as gatekeepers

This makes transparency and fairness more than technical concerns — they are economic necessities.


How Recommendation Algorithms Work: Cultural Impact of Recommendation Systems

Over time, recommendation algorithms influence culture itself.

They shape:

  • Trends
  • Language
  • Humor
  • Political discourse
  • Social norms

What surfaces repeatedly becomes normalized.

This long-term cultural shaping is one of the least understood effects of personalization systems.


How Recommendation Algorithms Work: Mental Models for Understanding Recommendation Algorithms

To truly understand how recommendation algorithms work, it helps to adopt the right mental models.


Mental Model 1: The Algorithm Is a Mirror

The system reflects:

  • Collective user behavior
  • Individual interaction patterns
  • Incentives built into its design

If something spreads, it is because the system learned that it “works.”


Mental Model 2: Recommendations Are Probabilities, Not Judgments

The system is not saying:

“This is good.”

It is saying:

“This is likely to produce a certain reaction.”

Understanding this removes the illusion of intent.


Mental Model 3: You Are Part of the Training Data

Every interaction:

  • Click
  • Pause
  • Skip
  • Watch
    feeds back into the system.

Users are not passive consumers — they are active participants in shaping recommendations.


How Recommendation Algorithms Work: Practical Insights for Users

Users can influence their recommendations more than they realize.

Effective actions include:

  • Actively engaging with desired content
  • Ignoring or skipping unwanted content
  • Using feedback tools when available
  • Understanding that short-term behavior has outsized impact

Small actions compound over time.


Practical Insights for Creators

Creators often misunderstand recommendation systems as arbitrary or hostile.

In reality:

  • Consistency builds stable embeddings
  • Audience alignment matters more than virality
  • Sudden pivots confuse models
  • Long-term engagement beats short-term spikes

Creators who understand system incentives adapt more effectively.


How Recommendation Algorithms Work: Design Lessons for Builders

For those building recommendation systems, the key lessons are clear:

  • Optimize for long-term value, not short-term metrics
  • Measure unintended effects
  • Include diversity and exploration by design
  • Treat trust as a core metric
  • Accept that perfect optimization is impossible

Resilience matters more than precision.


How Recommendation Algorithms Work: How All Support Articles Fit Into This Pillar

This pillar article provides the conceptual framework.

Each support article deepens one component:

  • Platform-specific recommendation systems
  • Ranking logic and scoring models
  • Collaborative vs content-based filtering
  • User embeddings
  • Feedback loops and system dynamics

Together, they form a complete understanding without redundancy.


How Recommendation Algorithms Work: Final Extended FAQs

Do recommendation algorithms understand meaning?
No. They model patterns, not meaning.

Can recommendation systems be neutral?
No system is neutral; objectives define outcomes.

Why do recommendations sometimes feel addictive?
Because systems optimize for engagement signals linked to habit formation.

Are recommendation algorithms getting better or worse?
Technically better, socially more complex.

Can regulation fully control recommendation systems?
Regulation can guide incentives, not eliminate trade-offs.

Will recommendation algorithms ever disappear?
Unlikely. They are now fundamental to digital scale.


Conclusion: How Recommendation Algorithms Work — Fully Understood

Recommendation algorithms are not mysterious forces. They are structured systems built on data, incentives, and feedback.

They:

  • Predict behavior
  • Shape attention
  • Influence culture
  • Redistribute opportunity

Understanding how recommendation algorithms work allows users, creators, and builders to interact with them more intentionally.

The future of the internet will not be defined by content alone — it will be defined by how that content is ranked, recommended, and reinforced.

And that makes recommendation literacy one of the most important skills of the modern age.

Many digital platforms that use recommendation algorithms also rely on subscription billing systems to monetize personalized content. These pricing systems are explained in how subscription pricing works .