
Feedback Loops in Recommendation Systems (Cause, Amplification, and Unintended Effects)

Feedback loops in recommendation systems explained: learn how ranking algorithms amplify behavior signals, reinforce content patterns, and create unintended system dynamics over time.

Feedback Loops in Recommendation Systems

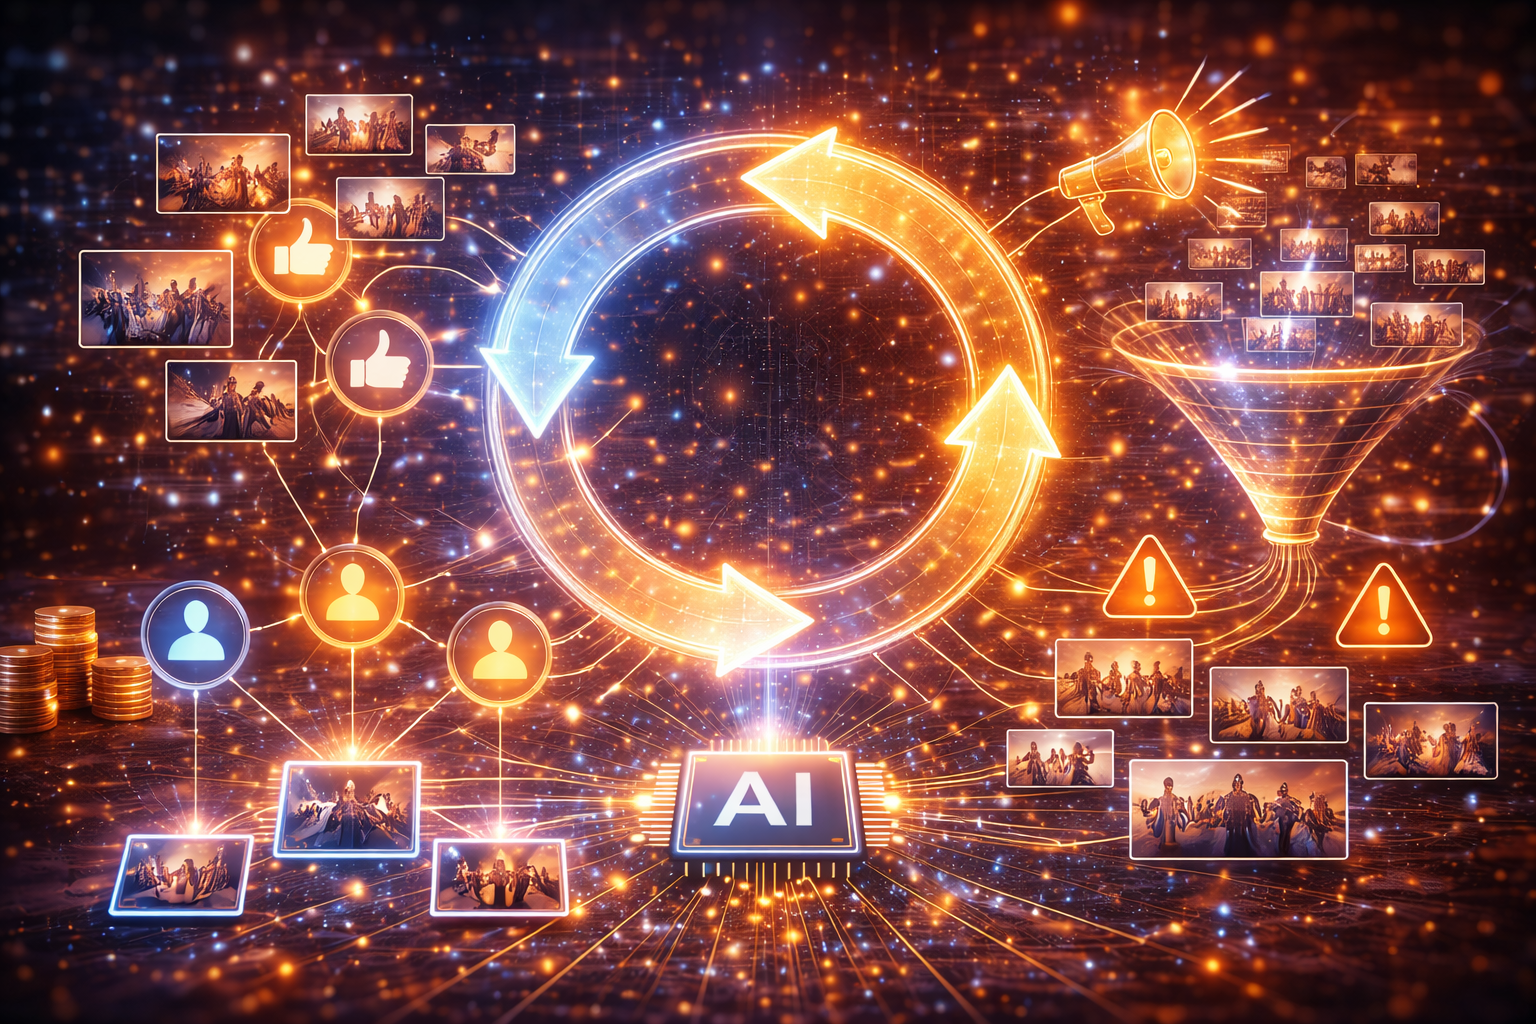
Feedback loops in recommendation systems occur when the outputs of a recommendation algorithm influence the data that the system later uses to train or update itself. In other words, what the system recommends today shapes what users interact with tomorrow, and those interactions become the training data that guides future recommendations.

Because recommendation systems rely heavily on behavioral signals—clicks, views, watch time, purchases, likes, shares, and other interactions—the system cannot observe user preferences independently of its own decisions. The content that users see is partly determined by the algorithm, and the data the algorithm learns from is partly determined by what it previously chose to show.

This creates a circular relationship between algorithm decisions and user behavior. That circular relationship is what produces feedback loops.

Feedback loops are fundamental to modern recommendation systems. They are not necessarily errors or flaws. In fact, feedback loops are often what allows recommendation systems to adapt quickly to user preferences. However, these loops can also produce unintended consequences, such as content concentration, popularity amplification, echo chambers, and recommendation drift.

Understanding feedback loops in recommendation systems requires examining how data flows through recommendation pipelines, how ranking algorithms learn from behavioral signals, and how system outputs influence future inputs.

Within the broader architecture of recommendation algorithms, feedback loops represent one of the most important system dynamics affecting how algorithms evolve over time.

Clear System Definition

A feedback loop in a recommendation system occurs when:

  1. the system recommends items
  2. users interact with those items
  3. the system records those interactions as training signals
  4. those signals influence future recommendation models
  5. future recommendations reflect those updated signals

The output of the system becomes part of the input that shapes the next generation of outputs.

This loop can be represented conceptually as:

Recommendation Output
→ User Interaction
→ Behavioral Data Collection
→ Model Training or Feature Update
→ New Recommendations

Because recommendation algorithms learn from interaction data, any influence the system has on user behavior will influence future recommendations.


Where Feedback Loops Appear

Feedback loops appear across many digital platforms.

Examples include:

Platform TypeFeedback Loop Example
Video platformsRecommended videos influence viewing history
Social mediaFeed ranking affects which posts receive engagement
Music streamingSuggested songs influence listening behavior
News platformsHeadlines shown affect article reading patterns
E-commerceProduct recommendations influence purchase data
Short-form video appsFeed ranking influences creator popularity

For example, if a video platform recommends a specific category of videos frequently, users may watch those videos simply because they are visible. Those views then become evidence that the category is popular with the user, causing the system to recommend more of the same category.

The algorithm is therefore not only predicting preferences—it is also shaping them.


The Basic Feedback Loop Cycle

At a simplified level, feedback loops in recommendation systems follow a recurring sequence.

Step 1: The system ranks candidate items.

Step 2: The system displays selected items to the user.

Step 3: The user interacts with some of the displayed items.

Step 4: The system records those interactions.

Step 5: The recorded interactions influence model updates or feature calculations.

Step 6: The system generates new recommendations based on updated signals.

Step 7: The cycle repeats.

This loop is continuous. Every user interaction contributes to the next round of recommendations.

The important implication is that the system is not observing neutral behavior. It is observing behavior within an environment that it helped construct.

Types of Feedback Loops

Feedback loops can take several forms depending on how the system uses interaction data.

The most common forms include:

  • reinforcement loops
  • popularity loops
  • exposure loops
  • preference shaping loops
  • data bias loops

Each operates slightly differently.


Reinforcement Feedback Loops

Reinforcement loops occur when the system interprets interactions with recommended content as evidence that similar content should be recommended again.

Example:

  1. System recommends several cooking videos.
  2. User clicks one of them.
  3. The algorithm records this interaction.
  4. The system increases the predicted relevance of cooking videos.
  5. More cooking videos appear in recommendations.

The user may continue interacting with cooking content simply because more of it appears.

Over time, this reinforces the category in the recommendation profile.

Reinforcement loops are the most common type of feedback loop in recommendation systems.

They help systems quickly adapt to user interests, but they can also cause content categories to dominate recommendations if signals accumulate repeatedly.


Popularity Amplification Loops

Popularity loops occur when items that receive early engagement gain additional exposure because they appear more popular.

Example:

  1. A newly uploaded video receives slightly above-average engagement.
  2. The ranking algorithm interprets this as a positive signal.
  3. The video receives additional recommendation exposure.
  4. More users watch it.
  5. Engagement increases further.
  6. The system promotes it even more.

This loop can lead to popularity amplification, where items that gain early traction receive disproportionate exposure.

The result is often described as a “rich get richer” effect.

Popularity amplification is common in:

  • social media feeds
  • trending video systems
  • viral content ranking
  • product marketplaces
  • news platforms

While popularity loops can help surface high-quality content quickly, they may also reduce exposure for new or niche items.


Exposure Feedback Loops

Exposure loops occur when items that are shown more often receive more interaction simply because they are visible.

Visibility itself influences interaction probability.

For example:

If a recommendation system displays two items:

ItemPositionLikelihood of Click
Item ATop positionHigh
Item BLower positionLower

Item A may receive more clicks not only because it is more relevant but also because it is more visible.

The system may then interpret the higher click rate as evidence that Item A is more relevant.

This reinforces the ranking.

Exposure loops therefore connect ranking decisions with engagement outcomes.


Preference Shaping Loops

Preference shaping loops occur when recommendations influence user preferences themselves.

Users do not always begin with fully formed interests.

Recommendation exposure can introduce new topics and categories.

Example:

  1. A platform recommends several documentary films.
  2. A user watches one out of curiosity.
  3. The user becomes interested in documentaries.
  4. The system recommends more documentaries.

In this case, the recommendation system helped shape the user’s preference rather than merely detect it.

Preference shaping is especially common in environments where users explore unfamiliar content, such as video platforms, music streaming, and news discovery systems.

Data Bias Loops

Data bias loops occur when the training data collected by a system becomes skewed due to earlier recommendation decisions.

For example:

If the system consistently recommends mainstream content more frequently than niche content, the training dataset will contain more interaction data for mainstream items.

Future models trained on this data may conclude that mainstream content is inherently more engaging.

However, this conclusion may partly reflect earlier exposure patterns rather than pure user preference.

Data bias loops can therefore reinforce structural biases in recommendation systems.


How Feedback Loops Affect Ranking Models

Ranking algorithms rely heavily on historical interaction data.

Common signals include:

  • click-through rate
  • watch duration
  • completion rate
  • likes and reactions
  • purchase conversion
  • dwell time
  • repeat interactions

When feedback loops alter the distribution of these signals, the ranking model may interpret the data as evidence of user preference.

However, some of the signal patterns may originate from earlier algorithm decisions rather than purely organic behavior.

For example:

A high click-through rate may reflect:

  • true user interest
  • strong recommendation positioning
  • popularity amplification
  • exposure bias

Ranking models must therefore attempt to distinguish between genuine preference signals and signals created by earlier ranking decisions.


Feedback Loops and Recommendation Drift

Feedback loops are one of the main reasons recommendations can drift over time.

If a system repeatedly reinforces a particular content category, that category may gradually dominate recommendations.

Example:

Initial state:

  • user watches mixed content

After several loops:

  • the system emphasizes one genre strongly

Eventually:

  • recommendations become heavily concentrated

This phenomenon is often described as recommendation drift.

Drift can occur even if the user initially interacted with the category only occasionally.


Echo Chambers and Content Narrowing

One widely discussed consequence of feedback loops is the formation of echo chambers.

An echo chamber occurs when recommendation systems repeatedly expose users to similar viewpoints, content categories, or themes.

The loop may follow this pattern:

  1. User interacts with a particular viewpoint.
  2. Algorithm interprets this as preference.
  3. More similar content appears.
  4. User interacts with that content again.
  5. The pattern repeats.

Over time, alternative perspectives may appear less frequently.

Echo chambers are particularly studied in:

  • social media platforms
  • political news distribution
  • opinion-based content feeds

This dynamic is especially visible in social media algorithms that prioritize posts based on engagement signals.

However, echo chambers are not solely caused by algorithms. They can also arise from user preference patterns and selective attention.

Recommendation feedback loops can amplify these tendencies.


Exploration as a Counterbalance to Feedback Loops

Many recommendation systems attempt to control feedback loops through exploration mechanisms.

Exploration introduces items that the system is uncertain about.

Instead of always showing the highest predicted items, the system occasionally tests new possibilities.

This allows the algorithm to collect new data.

Example exploration strategies include:

  • inserting novel items into recommendation rows
  • boosting newly uploaded content
  • rotating content categories
  • introducing diversity constraints
  • sampling items with uncertain scores

Exploration reduces the risk that the system becomes trapped in a narrow reinforcement cycle.

However, exploration must be balanced carefully because too much exploration can reduce recommendation relevance.


Feedback Loops and System Objectives

Recommendation systems often optimize multiple objectives simultaneously.

These may include:

  • engagement
  • satisfaction
  • retention
  • diversity
  • discovery
  • fairness
  • content coverage

Feedback loops can affect these objectives differently.

For example:

Optimizing for engagement alone may strengthen reinforcement loops because highly engaging content receives more exposure.

Optimizing for diversity may weaken reinforcement loops because the system intentionally introduces variety.

Platform designers therefore adjust ranking objectives to influence the strength of feedback loops.


Long-Term vs Short-Term Feedback Effects

Feedback loops can operate at multiple timescales.

Short-term loops occur within individual sessions.

Example:

  • user watches several videos on a topic
  • system temporarily increases similar recommendations

Long-term loops occur across weeks or months.

Example:

  • repeated engagement with a genre
  • gradual specialization of recommendation profile

Long-term loops are often responsible for stable user preference modeling.

Short-term loops help adapt recommendations quickly within sessions.

Both types interact to shape recommendation behavior.


Feedback Loops in Different Platform Types

Different platforms experience feedback loops in different ways.

Video platforms often experience strong reinforcement loops because watch time signals strongly influence ranking, as seen in systems such as Netflix recommendations.

Music streaming platforms may show preference shaping loops as users discover new genres.

E-commerce platforms experience popularity loops when highly purchased items become more visible.

News platforms may experience exposure loops due to headline placement and trending topics.

Although the underlying mechanisms are similar, the observable effects differ depending on platform design.


System Designers and Feedback Loop Management

Engineers designing recommendation systems actively monitor feedback loops.

Metrics that may indicate strong feedback effects include:

  • content diversity metrics
  • category concentration
  • creator exposure distribution
  • engagement concentration
  • long-tail content visibility

If feedback loops become too strong, platforms may introduce interventions such as:

  • stronger exploration policies
  • diversity constraints
  • popularity normalization
  • fairness-aware ranking
  • recommendation resets

These interventions help maintain a healthy recommendation ecosystem.


Interaction With Other Recommendation Concepts

Feedback loops connect closely with several other recommendation system concepts.

They interact with:

Feedback loops also influence why recommendations change over time, which was explained in the previous article in this cluster.

Together, these mechanisms shape how recommendation systems evolve.


FAQ: Feedback Loops in Recommendation Systems

Do recommendation systems create feedback loops intentionally?

Not always intentionally, but feedback loops naturally emerge when systems learn from user interactions.

Are feedback loops always harmful?

No. They help systems adapt quickly to user preferences. Problems arise when loops become too strong or too narrow.

Why do recommendation systems sometimes repeat similar content?

Repeated signals from user interactions can reinforce certain categories, causing the algorithm to recommend similar items more often.

Can feedback loops be controlled?

Yes. Platforms can use exploration strategies, diversity constraints, and model adjustments to moderate feedback effects.

Do all recommendation systems have feedback loops?

Most systems that learn from user behavior experience some form of feedback loop.

For deeper research on recommendation system dynamics and feedback effects, you can reference:

https://netflixtechblog.com

The Netflix technical blog often discusses personalization infrastructure and large-scale recommendation system design.

Conclusion

Feedback loops in recommendation systems are a natural consequence of learning from user behavior. When recommendation algorithms influence the content users see, those recommendations shape user interactions. Those interactions then become the data that informs future recommendations.

This circular relationship allows recommendation systems to adapt quickly to changing preferences, but it can also produce unintended effects such as popularity amplification, content concentration, and preference drift.

Understanding feedback loops helps explain why recommendation systems evolve over time and why recommendation outputs are influenced not only by user preferences but also by the system’s own past decisions.

As digital platforms continue to rely on recommendation systems for content discovery, managing feedback loops will remain a central challenge in designing stable, fair, and adaptive ranking systems.
How YouTube Recommendations Work: A Deep, Practical Breakdown of the YouTube Algorithm

How YouTube Recommendations Work and Why YouTube Recommendations Deserve a Full Breakdown

Understanding how YouTube recommendations work is not optional if you care about visibility, influence, or digital media literacy.

YouTube is no longer a simple video-hosting platform. It is one of the largest personalization engines ever built, shaping what billions of people watch, learn, and believe every day.

More than 70% of watch time on YouTube comes from recommendations, not search. That single fact changes everything.

This article explains YouTube’s recommendation system from the inside out — not from rumors, shortcuts, or outdated advice — but from how large-scale recommendation systems actually function.

How YouTube Recommendations Work: What the YouTube Recommendation System Is Actually Optimizing For

A common misconception is that YouTube optimizes for:

  • Views
  • Clicks
  • Virality

It does not.

At a system level, YouTube optimizes for:

Long-term viewer satisfaction across sessions

This means the system evaluates not just what you watch, but:

  • How long you stay
  • Whether you return tomorrow
  • Whether recommendations improve your experience over time

This framing explains why many “viral” videos fail to sustain distribution.


How YouTube Recommendations Work: Where YouTube Recommendations Appear

Recommendations power nearly every surface on YouTube:

  • Home feed
  • Suggested videos (Up Next)
  • Autoplay
  • End screens
  • Notifications (partially)
  • Shorts feed

Each surface uses different ranking models, but they share the same underlying logic and data sources.

If you’re interested in how short-form recommendation differs, see our breakdown of how TikTok’s For You algorithm works , where content velocity and rapid feedback loops play a larger role.

The Two-Stage Architecture Behind YouTube Recommendations

YouTube does not rank all videos at once. That would be computationally impossible.

Instead, it uses a two-stage architecture.


How YouTube Recommendations Work Stage 1: Candidate Generation

Candidate generation answers one question:

“Which videos are even worth considering for this user right now?”

From billions of videos, YouTube narrows the pool to hundreds or thousands.

Candidate sources include:

  • Watch history similarity
  • Previously watched channels
  • Topic-based similarity
  • Popular content among similar users
  • Fresh uploads
  • Shorts exploration pools

This stage prioritizes speed over precision.


How YouTube Recommendations Work Stage 2: Ranking

Ranking answers a different question:

“In what order should these videos be shown to maximize satisfaction?”

Each candidate video is scored using machine learning models that estimate:

  • Probability of watching
  • Expected watch time
  • Likelihood of satisfaction
  • Risk of dissatisfaction
  • Session continuation value

The final feed is personalized per user, per moment.

How YouTube Recommendations Work: The Most Important Signals in YouTube Recommendations (Explained Properly)

There is no single “magic metric.”

YouTube combines dozens of signals, weighted differently depending on context.


Watch Time (With Nuance)

Watch time matters — but not in isolation.

YouTube evaluates:

  • Watch time relative to video length
  • Watch time compared to similar videos
  • Whether viewers keep watching afterward

A short video with high completion can outperform a longer one.


Session-Level Value

One of YouTube’s most important but least discussed concepts is session value.

The system tracks:

  • Does this video extend a session?
  • Does it end a session?
  • Does it lead to further satisfaction?

Videos that keep users on YouTube happily are rewarded.


Viewer Satisfaction Signals

YouTube explicitly measures satisfaction using:

  • Likes and dislikes
  • Viewer surveys
  • “Not interested” actions
  • Long-term return behavior

This is how YouTube counteracts pure clickbait.


Engagement Signals (Secondary but Reinforcing)

  • Comments
  • Shares
  • Subscriptions gained
  • Playlist additions

Engagement supports distribution, but only if watch behavior is strong.


How YouTube Recommendations Work Personalization: Why There Is No Single YouTube Algorithm

There is no universal YouTube feed.

Each user has:

  • A unique watch history
  • Individual interest embeddings
  • Different tolerance for novelty
  • Different satisfaction thresholds

The same video can:

  • Explode for one audience
  • Be invisible to another

Creators often misinterpret this as randomness. It is not.


How YouTube Recommendations Work: Early Feedback Loops and the “First Audience” Effect

Every video begins with a small test audience.

YouTube observes:

  • Click behavior
  • Watch depth
  • Satisfaction indicators

If the first audience responds positively, the system expands distribution to similar viewers.

If not, distribution slows — often permanently.

This makes audience alignment more important than broad appeal.

How YouTube Recommendations Work: Why YouTube Recommendations Change Over Time

Creators often say:

“The algorithm changed.”

Most of the time, what actually changed is:

  • Viewer expectations
  • Competing content
  • Topic saturation
  • Seasonal interest
  • Relative performance

YouTube’s models update constantly, but stability comes from consistent satisfaction, not tactics.


How YouTube Recommendations Work: Short-Term Spikes vs Long-Term Distribution

YouTube distinguishes between:

  • Initial performance
  • Sustained performance

Videos that:

  • Age well
  • Maintain relevance
  • Continue satisfying viewers

Can resurface months or years later.

This is why evergreen content matters.

How YouTube Recommendations Work: Long-Form Videos vs Shorts: Two Recommendation Systems Under One Roof

Although both appear on the same platform, long-form videos and Shorts are governed by different recommendation dynamics.

They share infrastructure, but not incentives.


Long-Form Video Recommendations

Long-form recommendations prioritize:

  • Session continuation
  • Sustained watch time
  • Viewer satisfaction across multiple videos
  • Return visits over days and weeks

The system asks:

“Does this video lead to a better overall viewing session?”

This explains why long-form videos can grow slowly and remain relevant for years.


Shorts Recommendations

Shorts operate on compressed feedback loops.

Key characteristics:

  • Extremely fast signal collection
  • Heavy reliance on completion rate
  • Rapid exploration of new creators
  • Less dependence on prior subscriptions

Shorts are optimized for immediate engagement, not long-term narrative arcs.

This is why Shorts can explode quickly — and disappear just as fast.

Why Shorts Success Doesn’t Always Transfer to Long-Form

Creators often assume Shorts success will boost long-form distribution. Sometimes it does — often it doesn’t.

Reasons include:

  • Different audience intent
  • Different satisfaction metrics
  • Different consumption patterns
  • Weak cross-format embeddings

In short: the system treats Shorts viewers and long-form viewers as different behavioral contexts.


How YouTube Recommendations Work: User Modeling on YouTube: How Viewers Are Represented

YouTube does not store users as simple profiles.

Instead, it uses dynamic user representations that evolve continuously.


Interest Embeddings

Each user is represented by multiple embeddings that encode:

  • Topic interests
  • Format preferences
  • Engagement intensity
  • Temporal behavior patterns

These embeddings update after nearly every interaction.


Why Small Actions Matter

Short interactions can disproportionately affect recommendations:

  • Skipping a video quickly
  • Watching one video twice
  • Ending a session early

These signals help the system infer what not to show as much as what to show.


Item Modeling: How Videos Are Understood

Videos are also represented as embeddings.

These representations incorporate:

  • Visual content
  • Audio features
  • Text metadata
  • Early viewer behavior
  • Audience retention patterns

The system does not “understand” meaning — it understands correlations.

How YouTube Recommendations Work: Exploration vs Exploitation on YouTube

YouTube constantly balances:

  • Exploitation (showing known favorites)
  • Exploration (testing new content)

How Exploration Works in Practice

Exploration appears as:

  • New channels in your feed
  • Slight topic deviations
  • Fresh uploads
  • Experimental Shorts

These tests are deliberate, not random.

If exploration content performs well, it becomes part of the user’s stable recommendation profile.


Why Over-Exploration Feels “Off”

If exploration overwhelms relevance:

  • Users feel confused
  • Satisfaction drops
  • Session length decreases

The system quickly corrects by reverting to safer recommendations.


The First 48 Hours: Early Distribution Mechanics

The first 24–48 hours of a video’s life are critical.

During this phase, YouTube evaluates:

  • Initial click behavior
  • Early watch depth
  • Satisfaction signals
  • Audience match quality

However, early performance is relative, not absolute.

A video is judged against:

  • Similar content
  • Similar channels
  • Similar audience sizes

This is why small channels can still succeed.


Why Videos Sometimes “Flatline”

A flatline usually means:

  • The test audience did not engage deeply
  • Retention dropped compared to peers
  • The video ended sessions
  • Negative feedback accumulated

This is not punishment — it is resource reallocation.


How YouTube Recommendations Work: Monetization-Aware Ranking (Without Myths)

YouTube does not rank purely for ads, but monetization constraints do exist.

Factors include:

  • Advertiser suitability
  • Content safety
  • Viewer trust
  • Brand risk

Videos that violate guidelines may still be recommended — but with reduced reach.


Trust, Safety, and Policy Constraints

Recommendation systems operate within hard boundaries.

Constraints include:

  • Misinformation policies
  • Harmful content detection
  • Age-appropriateness
  • Legal requirements

These constraints override pure engagement optimization.

How YouTube Recommendations Work: Why “Shadowbanning” Is the Wrong Mental Model

Creators often interpret drops in reach as shadowbans.

In practice:

  • Distribution is performance-based
  • Audience interest shifts
  • Competition increases
  • Relative metrics change

There is no need for hidden suppression when automated ranking already reallocates attention efficiently.


Common Creator Failure Modes

Understanding failure modes helps avoid them.


Failure Mode 1: Misaligned Thumbnails

High click, low watch time = negative signal.


Failure Mode 2: Audience Drift

Sudden topic shifts confuse user embeddings.


Failure Mode 3: Chasing Trends Blindly

Trend saturation lowers relative performance.


Failure Mode 4: Optimizing for One Metric

Watch time without satisfaction leads to decay.


Why Consistency Actually Matters

Consistency helps the system:

  • Predict audience match
  • Build stable embeddings
  • Reduce exploration risk

This does not mean repeating content — it means maintaining audience clarity.


Why Some Old Videos Suddenly Resurface

Resurfacing occurs when:

  • Topic relevance returns
  • New audience clusters emerge
  • Seasonal interest spikes
  • Model updates re-rank content

Evergreen videos are stored, not forgotten.


Advanced Myths (Debunked)

Myth: Uploading daily boosts recommendations
Reality: Viewer satisfaction dominates frequency

Myth: Deleting videos hurts the channel
Reality: Minimal impact unless patterns are extreme

Myth: External traffic hurts recommendations
Reality: Only if it reduces satisfaction


Mental Model: Think in Distributions, Not Decisions

The system does not “decide” a video’s fate.

It continuously updates probability distributions:

  • Who might like this?
  • How likely are they to watch?
  • What happens after?

This probabilistic framing explains all observed behavior.

How YouTube Measures “Success” Internally (Beyond Surface Metrics)

Creators see metrics like views, watch time, and click-through rate.
YouTube’s recommendation system sees something more abstract: expected value.

Instead of asking:

“Did this video do well?”

The system asks:

“How valuable was this video for this viewer compared to alternatives?”

This comparison-based framing explains many counterintuitive outcomes.


Relative Performance, Not Absolute Numbers

A common misunderstanding is assuming high numbers automatically mean success.

In reality, performance is judged relative to peers, such as:

  • Videos of similar length
  • Videos on similar topics
  • Videos shown to similar audiences
  • Videos from similar-sized channels

A video with:

  • 10,000 views can be a success
  • 1 million views can be a failure

It depends on what the system expected.


How YouTube Recommendations Work: Ranking Metrics as Trade-Offs, Not Targets

YouTube does not optimize one metric at a time.

It balances multiple competing objectives, including:

  • Watch time
  • Satisfaction
  • Retention
  • Diversity
  • Safety
  • Exploration

Improving one metric at the expense of others often backfires.


Why Click-Through Rate Alone Is Dangerous

High CTR with low watch depth signals:

  • Misleading packaging
  • Audience mismatch
  • Poor expectation setting

The system learns to trust watch behavior over clicks.


Why Watch Time Alone Isn’t Enough

High watch time with:

  • Session endings
  • Negative feedback
  • Viewer fatigue

Can still lose distribution.

This is why YouTube emphasizes long-term satisfaction.


Multi-Objective Optimization (Without the Math)

Internally, YouTube’s ranking models learn to trade off objectives.

Conceptually:

  • Each video has strengths and weaknesses
  • The system chooses acceptable compromises
  • No video maximizes everything

This is why:

  • Some videos are great for discovery
  • Others are great for retention
  • Others serve niche audiences

Different videos win in different contexts.


How YouTube Evaluates Creator Reliability

Beyond individual videos, YouTube builds models of creator reliability.

This does not mean favoritism.

It means estimating:

  • How predictable viewer satisfaction is
  • How often content meets expectations
  • How risky recommendations might be

Creators with consistent audience alignment are easier to recommend confidently.


Why Consistency Reduces Risk

From the system’s perspective:

  • Consistent creators reduce uncertainty
  • Reduced uncertainty improves ranking confidence
  • Confidence allows broader testing

This is why erratic pivots often reduce reach temporarily.


Channel-Level vs Video-Level Dynamics

A critical distinction many creators miss:

  • Videos compete against videos
  • Channels build reputations over time

A single underperforming video does not “kill” a channel.
But repeated misalignment increases system uncertainty.


Why Some Channels Plateau

Plateaus often occur when:

  • Audience size stabilizes
  • Topic saturation increases
  • Marginal viewers are less interested
  • Competition intensifies

This is not punishment — it’s market equilibrium.

Breaking plateaus usually requires:

  • New audience segments
  • Format innovation
  • Deeper value, not broader appeal

Explaining “Algorithm Favoritism” Without Conspiracies

When some creators consistently perform well, it can look like favoritism.

What’s actually happening:

  • The system has high confidence in audience satisfaction
  • Distribution risk is low
  • Performance variance is predictable

This is statistical trust, not preference.


How YouTube Handles Uncertainty

Uncertainty is expensive.

The system must decide:

  • Should this video be tested further?
  • Is the risk worth the potential reward?
  • Will this harm user trust?

When uncertainty is high, exploration is conservative.

Long-Term Channel Growth as a Systems Problem

Successful channels align with the system rather than fighting it.

Long-term growth emerges from:

  • Stable audience signals
  • Clear value proposition
  • Predictable satisfaction
  • Periodic innovation

Growth is not linear — it is phase-based.


Growth Phase 1: Audience Discovery

  • Heavy exploration
  • High volatility
  • Inconsistent distribution

Growth Phase 2: Audience Fit

  • Stabilizing metrics
  • Improving retention
  • Narrowing audience definition

Growth Phase 3: Optimization

  • Predictable performance
  • Slower growth
  • Strong loyalty

Growth Phase 4: Expansion or Decline

  • Expand thoughtfully → new growth curve
  • Stay static → plateau
  • Misalign → decline

Understanding these phases prevents misinterpretation of normal cycles.


Why “Going Viral” Is Not a Strategy

Virality is a side effect, not a plan.

Viral spikes often:

  • Attract misaligned viewers
  • Damage long-term metrics
  • Increase churn
  • Reduce system confidence

Sustainable growth comes from repeat satisfaction, not spikes.


Audience Matching: The Most Underrated Factor

The system prioritizes who sees a video more than how many see it.

A perfectly matched small audience:

  • Outperforms a poorly matched large one
  • Produces stronger feedback loops
  • Enables broader distribution later

This is why niche clarity often beats broad appeal.


Why Metadata Matters Less Than People Think

Titles, thumbnails, and descriptions help:

  • Set expectations
  • Enable discovery
  • Improve early clicks

But they cannot override:

  • Poor watch behavior
  • Audience mismatch
  • Low satisfaction

Metadata opens the door — behavior decides what happens next.


Advanced Failure Case: The “Good Metrics, Bad Growth” Trap

Some creators see:

  • High watch time
  • Good CTR
  • Strong engagement

Yet growth stalls.

Common reasons:

  • Audience too narrow
  • Limited scalability
  • Low session continuation
  • High redundancy

The system sees no reason to expand further.


Strategic Takeaways for Advanced Creators

Think in terms of:

  • Audience alignment, not hacks
  • Systems, not switches
  • Probabilities, not promises
  • Long-term trust, not short-term spikes

Creators who understand the system stop asking:

“What does the algorithm want?”

And start asking:

“What experience am I consistently delivering?”

Shorts ↔ Long-Form Crossover: What Actually Transfers (and What Doesn’t)

One of the most misunderstood topics on YouTube is whether success in Shorts helps long-form videos.

The answer is nuanced.


What Transfers Successfully

Some signals do carry over:

  • Channel-level recognition
  • Brand familiarity
  • Viewer curiosity
  • Creator reliability (weakly)

If Shorts viewers intentionally click into long-form and watch deeply, positive transfer occurs.

What Does Not Transfer Automatically

Most Shorts signals do not translate cleanly:

  • Completion rate
  • Swipe behavior
  • Rapid feedback loops
  • Passive consumption patterns

Shorts success alone does not redefine long-form audience embeddings.


Why This Matters Strategically

Creators should treat Shorts as:

  • A discovery surface
  • A testing ground for ideas
  • A brand awareness channel

Not as a shortcut to long-form growth.


Safe Experimentation Without Damaging Your Channel

Experimentation is necessary — but reckless experimentation confuses the system.


Why Sudden Pivots Are Risky

Sudden changes can:

  • Disrupt audience embeddings
  • Increase uncertainty
  • Reduce recommendation confidence

The system doesn’t “punish” — it hesitates.


How to Experiment Safely

Best practices:

  • Experiment within adjacent topics
  • Use secondary formats or series
  • Gradually shift audience expectations
  • Watch who responds, not just how many

Think evolution, not reinvention.


Why Recommendation Systems Fail Gracefully (Most of the Time)

Despite their power, YouTube’s recommendation systems are designed to fail safely.


Graceful Failure Mechanisms

These include:

  • Limited initial testing
  • Gradual rollout
  • Performance thresholds
  • Human oversight
  • Safety constraints

This prevents catastrophic amplification of low-quality or harmful content.


Why This Protects Creators Too

Graceful failure means:

  • One bad video doesn’t end a channel
  • Experiments don’t permanently define you
  • Recovery is possible with alignment

The system is cautious by design.

The Most Accurate Mental Model of the YouTube Algorithm

After everything covered in this guide, the most accurate mental model is this:

YouTube is a large-scale prediction system optimizing for long-term viewer satisfaction under uncertainty and constraints.

It is not:

  • A rulebook
  • A scorecard
  • A judge
  • An enemy

It is a probabilistic engine making trade-offs at scale.


Why Creators Who “Crack the Algorithm” Often Burn Out

Creators chasing the algorithm tend to:

  • Over-optimize
  • Lose authenticity
  • Chase metrics over meaning
  • Confuse short-term gains with strategy

Creators who align with viewers:

  • Grow slower
  • Grow steadier
  • Last longer

Longevity is the real optimization.


System Literacy vs Algorithm Anxiety

Most creator frustration comes from misattribution.

Normal phenomena mistaken for algorithmic punishment:

  • Audience fatigue
  • Topic saturation
  • Competition growth
  • Platform maturity

Understanding the system replaces anxiety with clarity.


What YouTube Recommendations Cannot Do

Despite their sophistication, recommendation systems cannot:

  • Read intent
  • Understand truth
  • Judge creativity
  • Guarantee success
  • Replace human taste

They respond to patterns — nothing more.


Extended Expert FAQs

Does uploading time affect recommendations?
Only marginally; relevance and satisfaction dominate.

Do comments boost ranking?
Only if they correlate with positive watch behavior.

Does deleting underperforming videos help?
Rarely; focus on future alignment instead.

Can channels recover from long declines?
Yes — but recovery requires genuine audience realignment.

Are smaller creators disadvantaged?
No. Relative performance matters more than size.

Is YouTube getting harder or just more competitive?
More competitive — not more hostile.


How This Support Article Complements the Pillar

This article answers the “how does this work in practice?” question.

The pillar article explains:

  • Recommendation systems as a class
  • Core mechanics across platforms
  • System-level trade-offs

This support article:

  • Applies those mechanics concretely to YouTube
  • Explains creator-facing consequences
  • Provides actionable mental models

Together, they form a coherent knowledge base.


Final Synthesis: How YouTube Recommendations Really Work

YouTube recommendations are not mysterious forces operating behind a curtain.

They are:

  • Data-driven
  • Behavior-based
  • Continuously adapting
  • Constraint-aware
  • Long-term oriented

Creators who succeed are not those who “game the system,”
but those who consistently deliver value to a clearly defined audience.

When audience satisfaction aligns with system incentives, growth becomes a byproduct — not a chase.

Conclusion

Understanding how YouTube recommendations work does not give you control.

It gives you context.

And with context:

  • You make better creative decisions
  • You interpret metrics correctly
  • You stop chasing myths
  • You build sustainably

That is the real advantage.

Streaming platforms often combine recommendation systems with subscription paywalls that control access to premium content. These access models are explained in how paywalls work .